

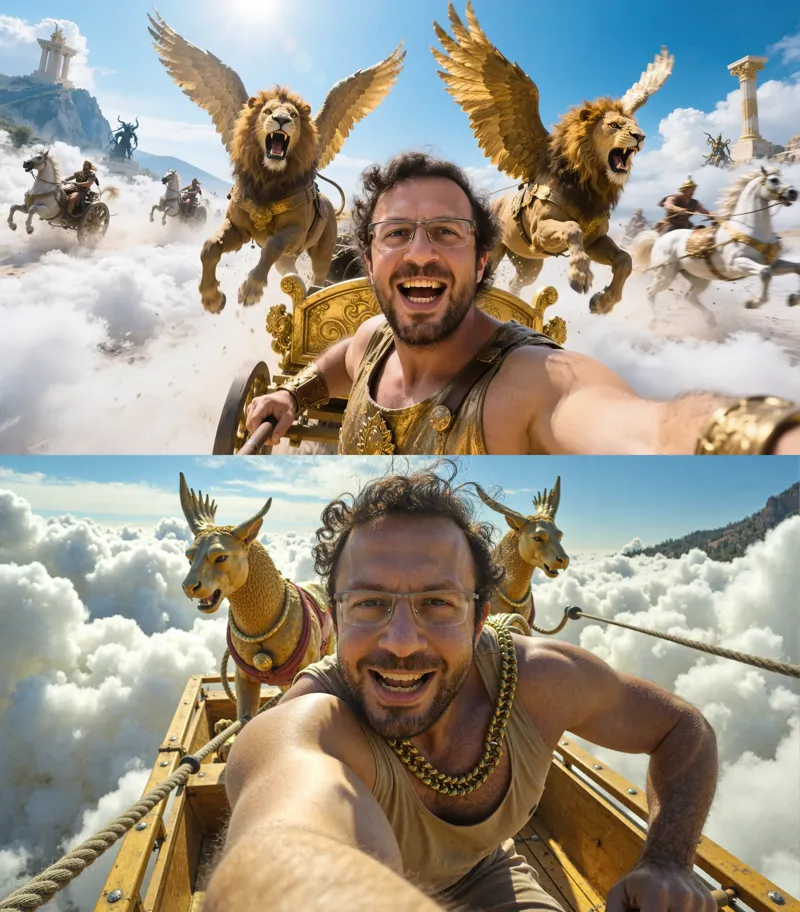


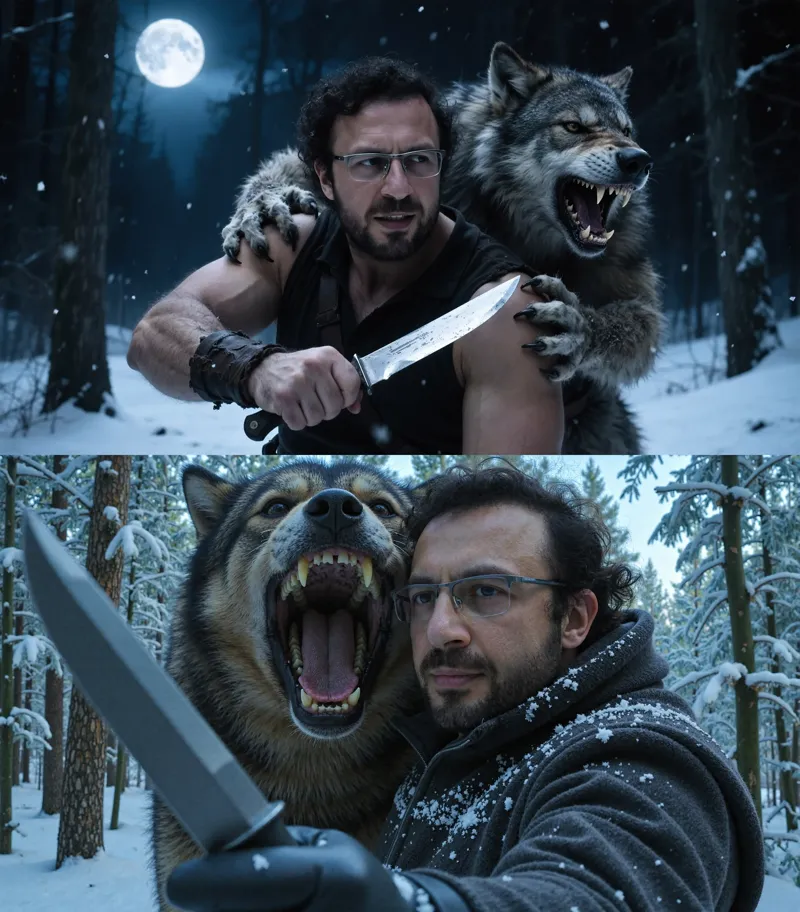
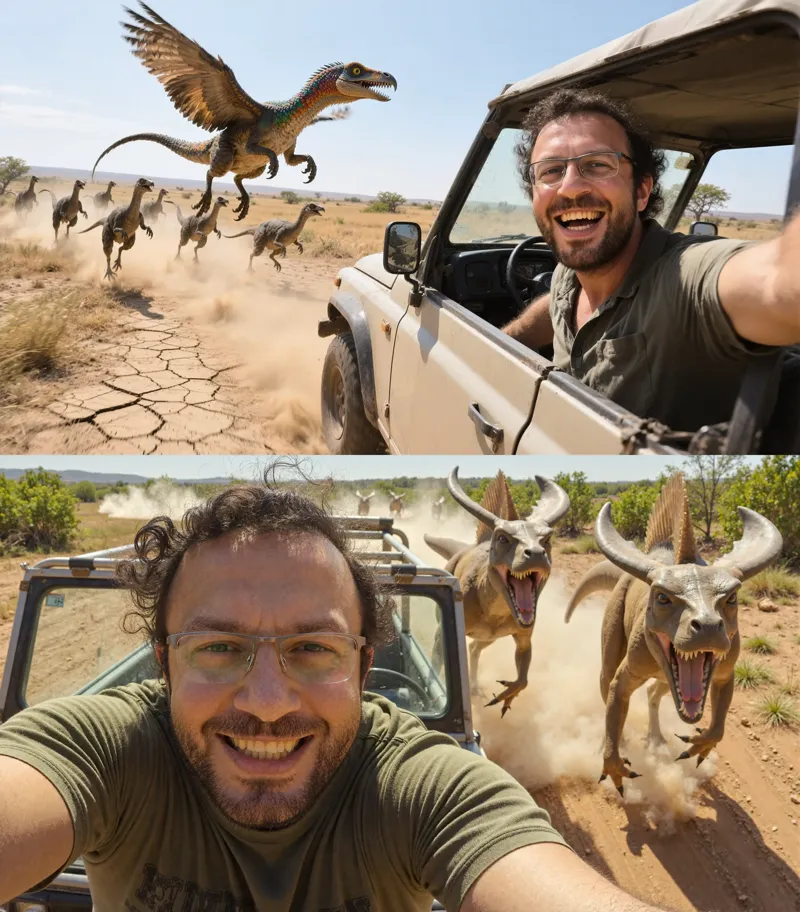
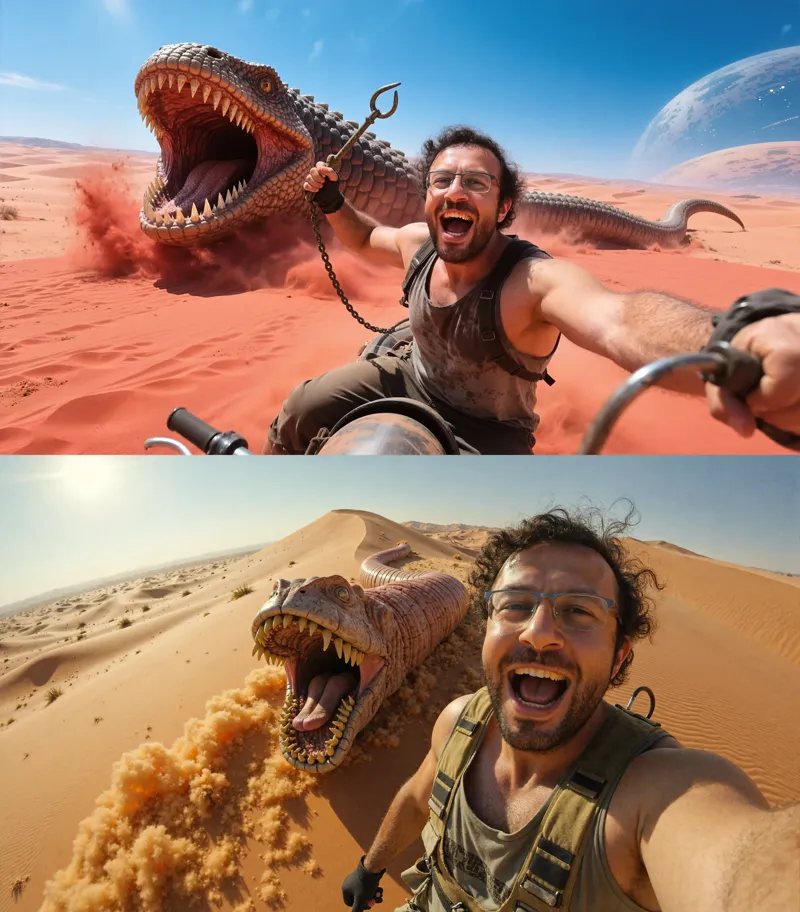


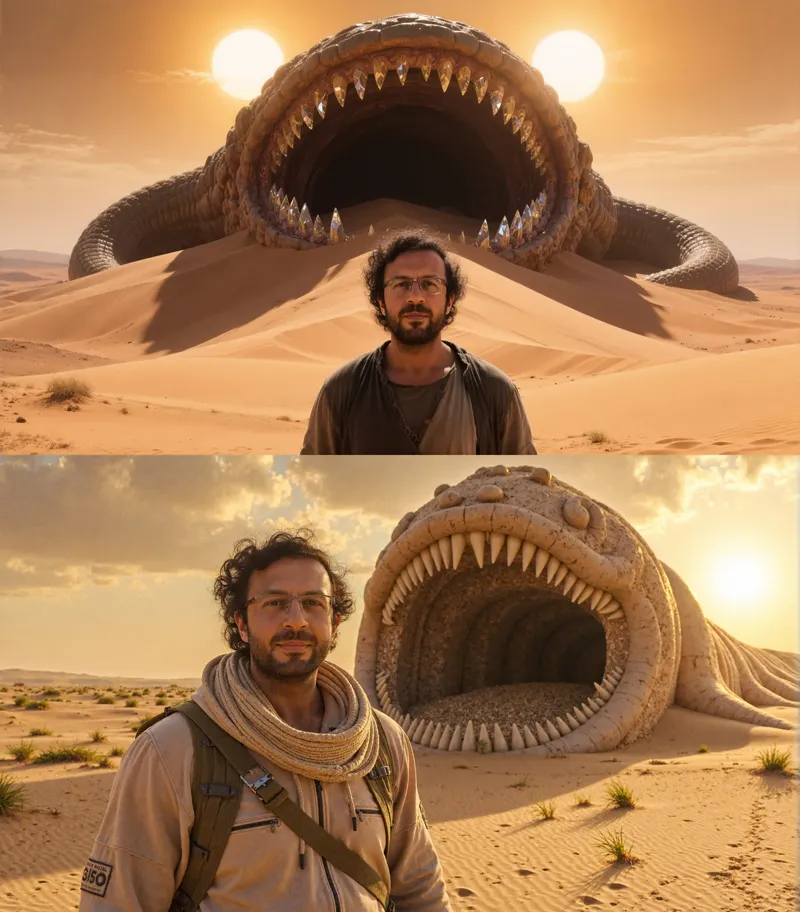
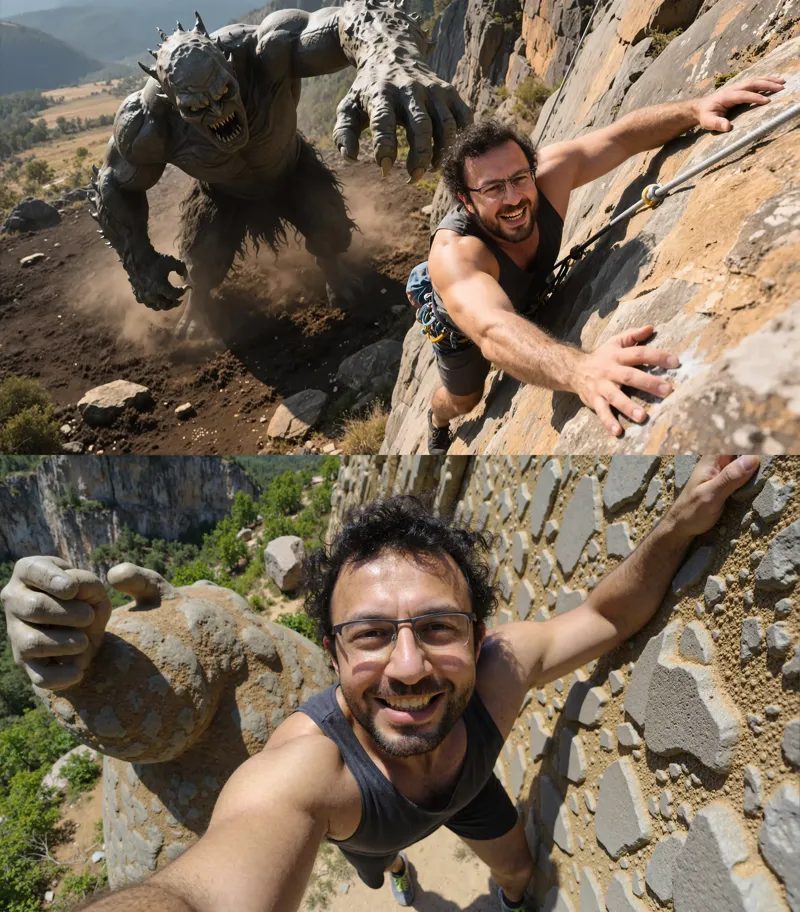

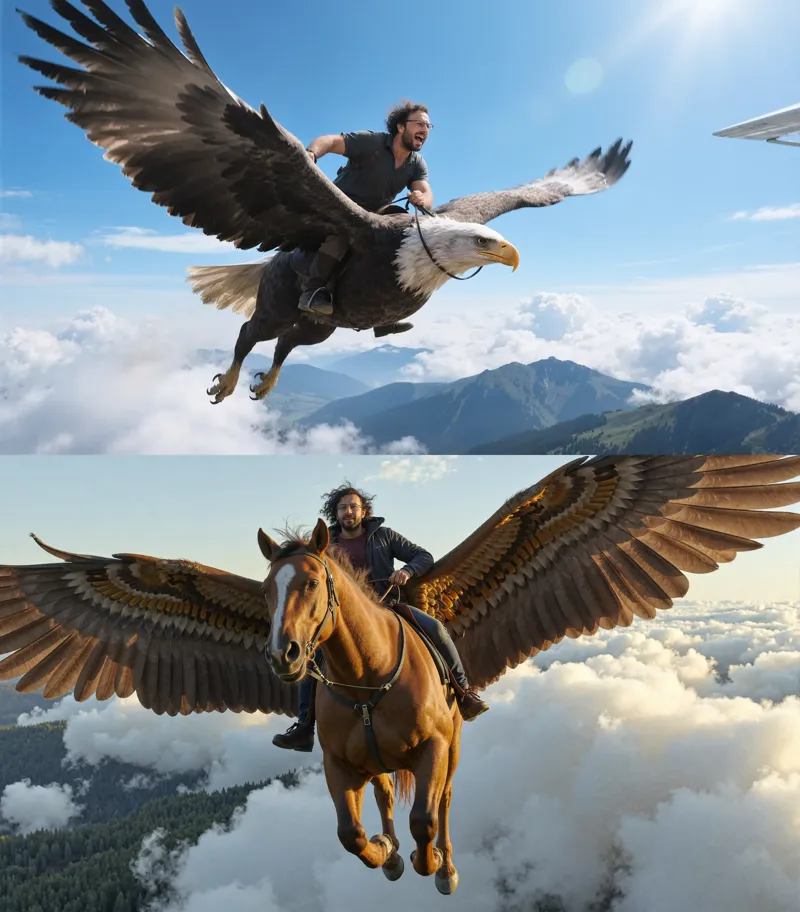
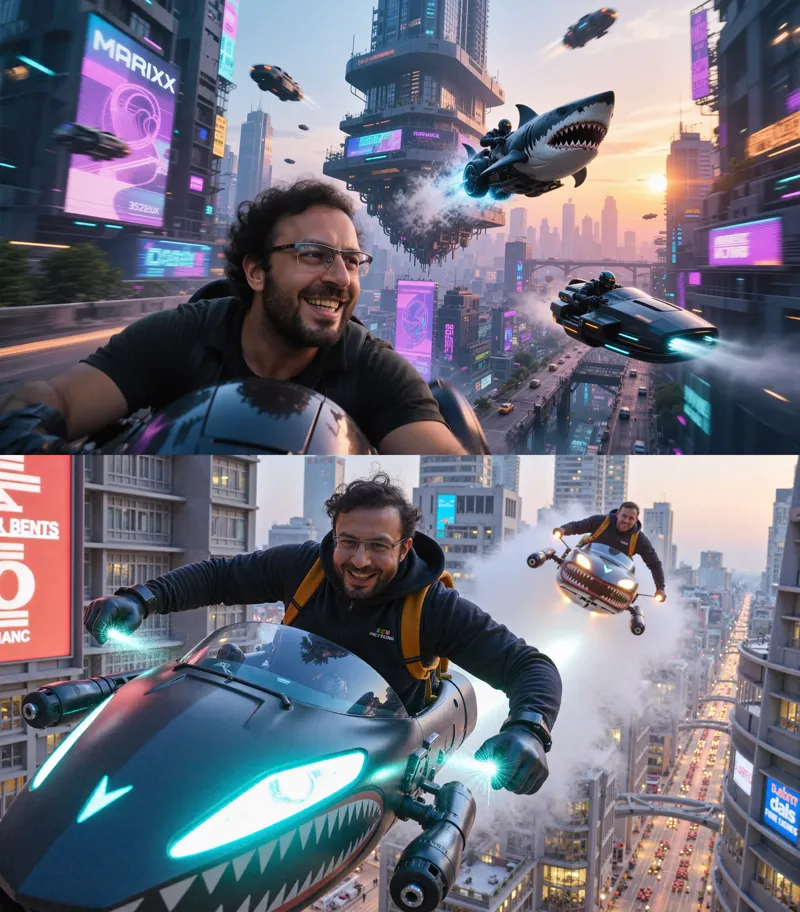
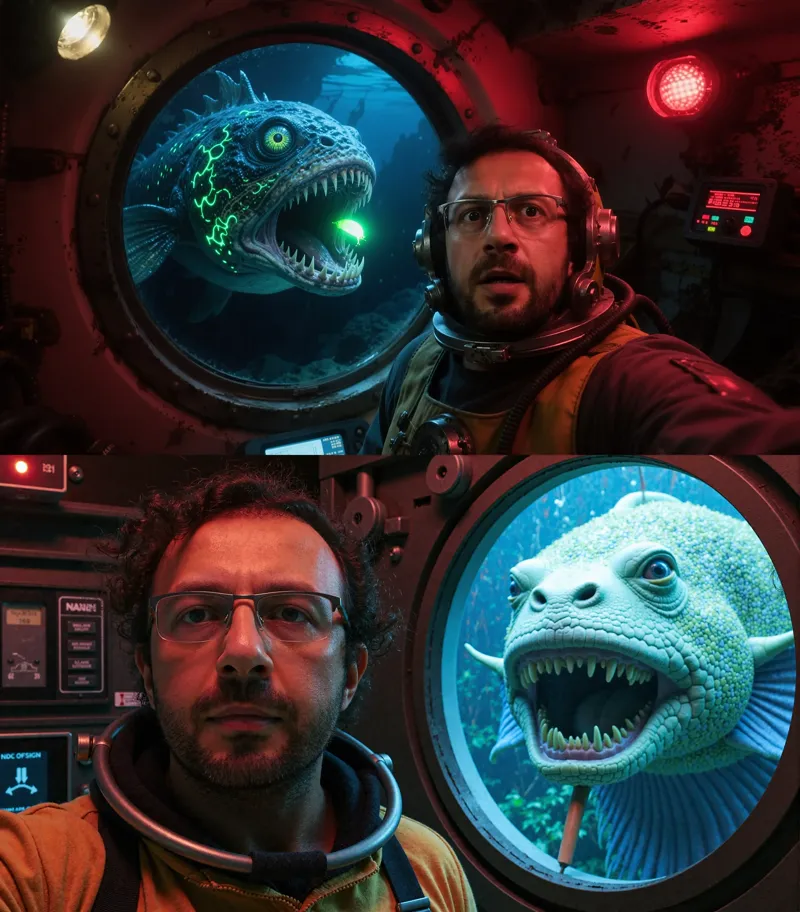

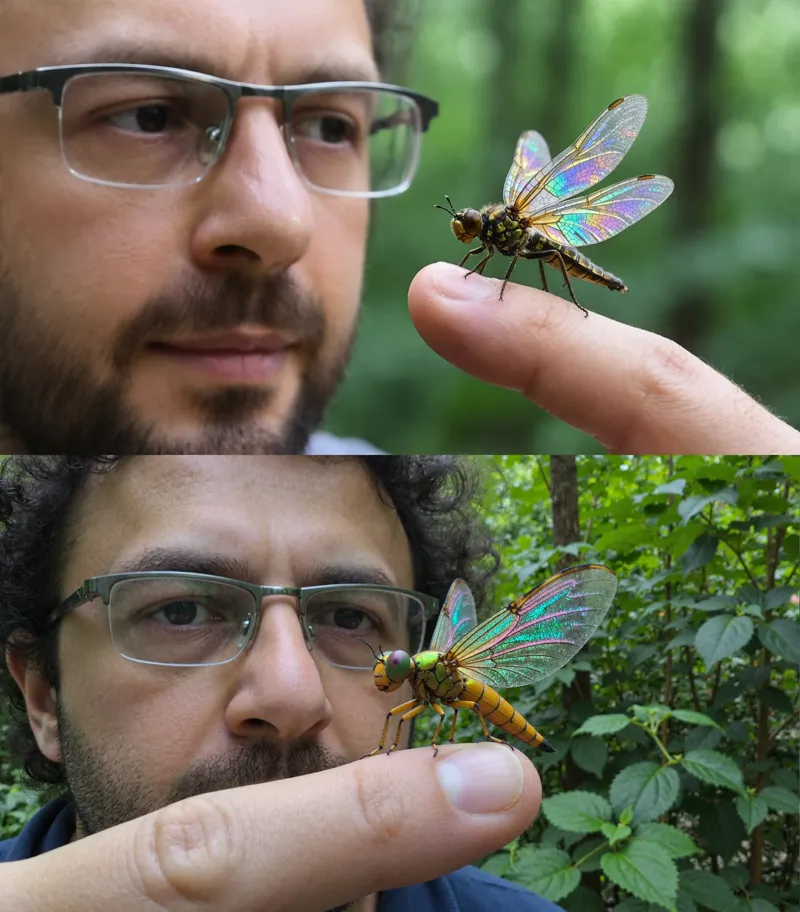


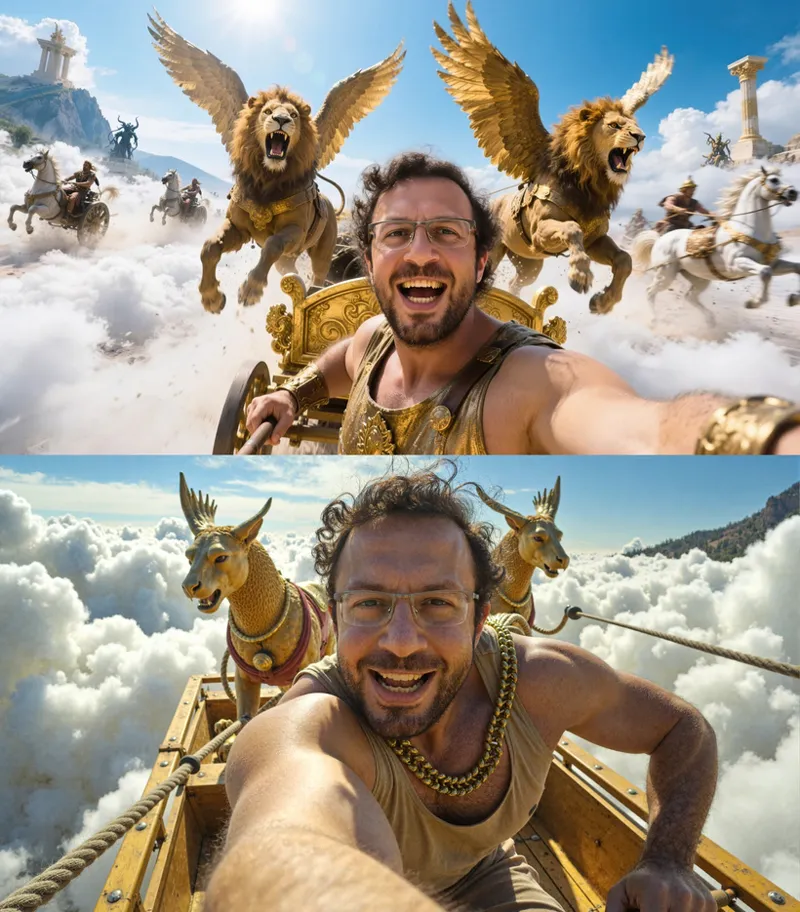


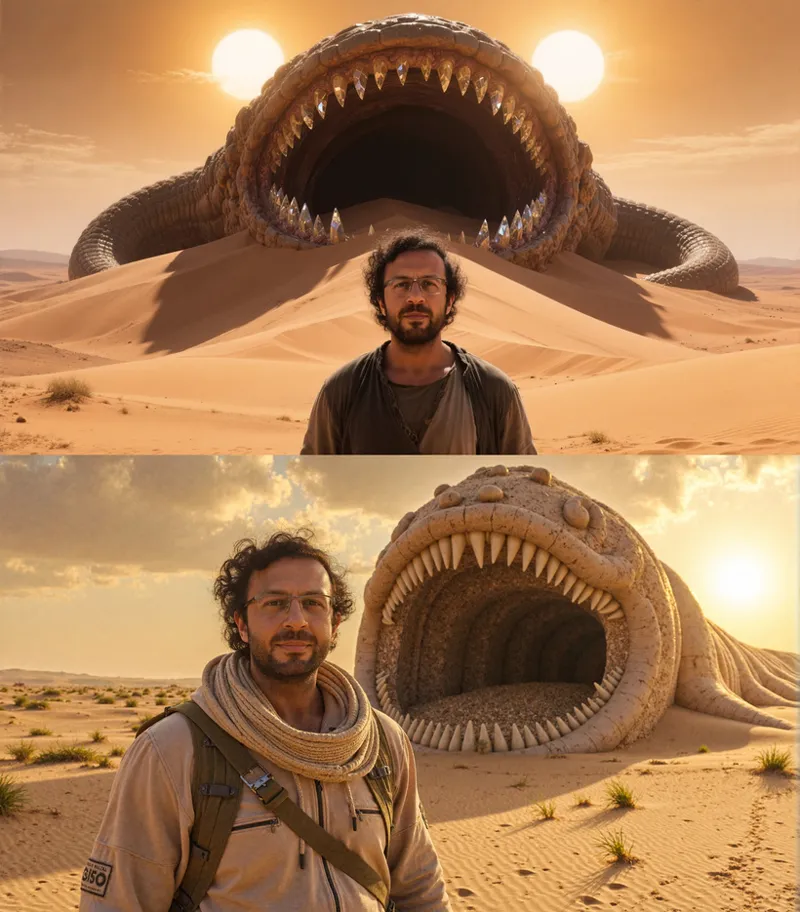


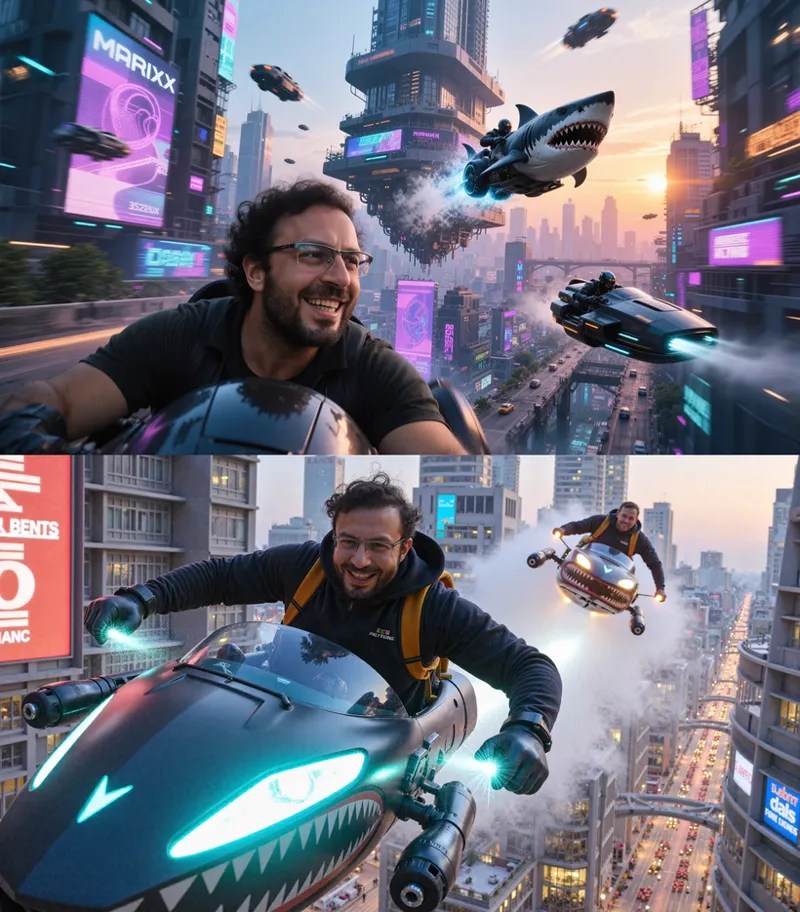


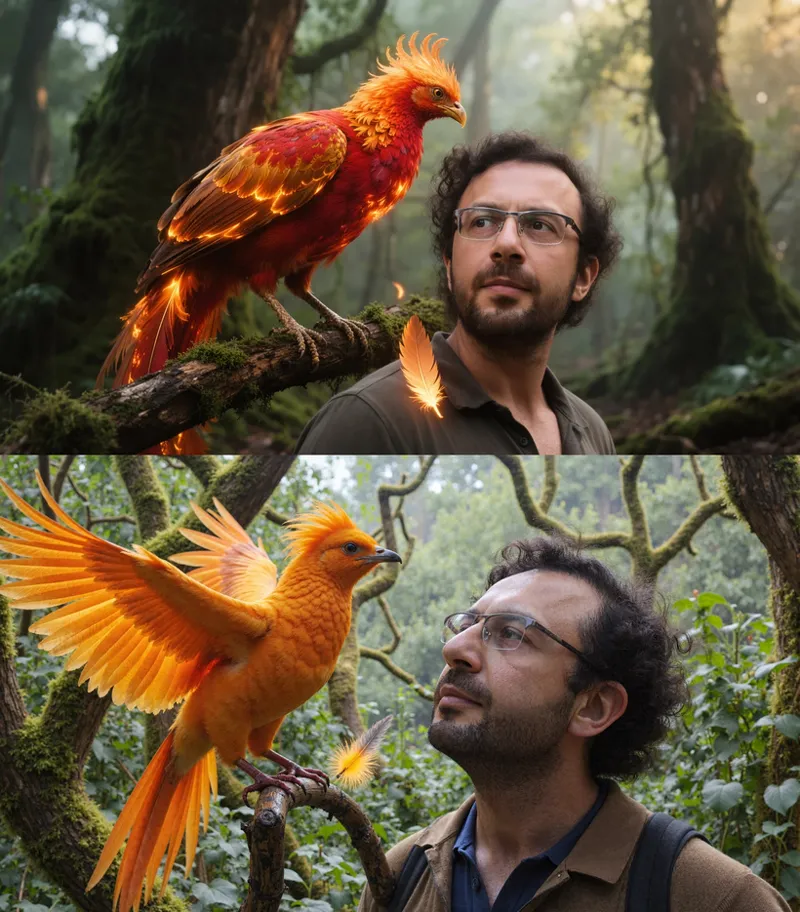


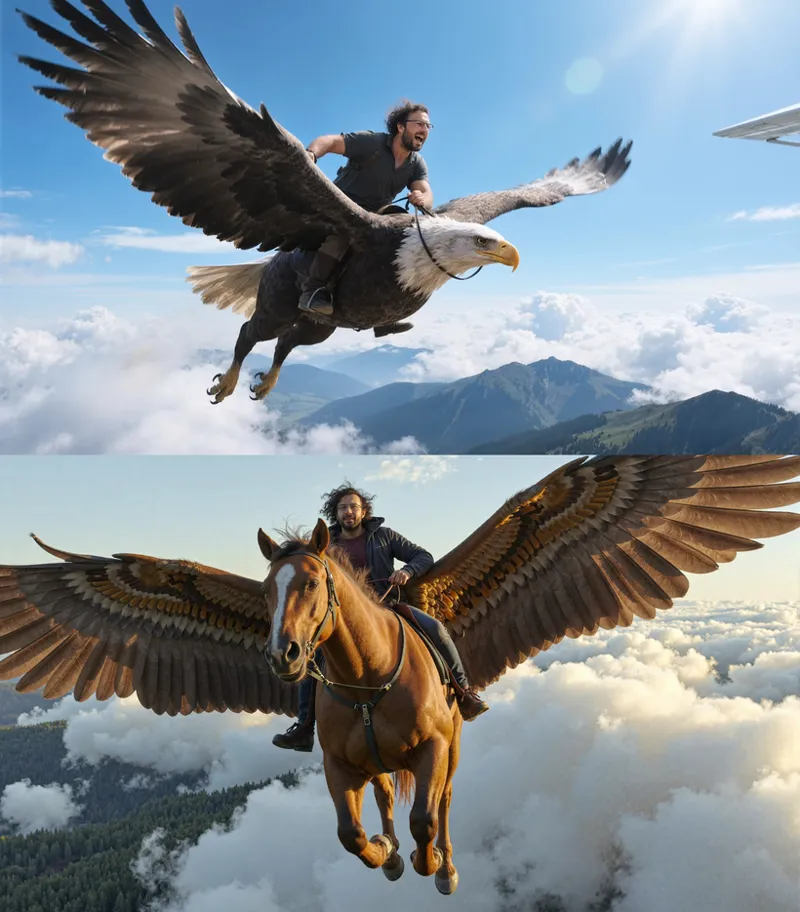


Qwen Image Base Model Training vs FLUX SRPO Training 20 images comparison (top ones Qwen bottom ones FLUX) - Same Dataset (28 imgs) - I can't return back to FLUX such as massive difference - Qwen destroys the FLUX at complex prompts and emotions
Full tutorial link > https://www.youtube.com/watch?v=DPX3eBTuO_Y
Info
This is a full comprehensive step-by-step tutorial for how to train Qwen Image models. This tutorial covers how to do LoRA training and full Fine-Tuning / DreamBooth training on Qwen Image models. It covers both the Qwen Image base model and the Qwen Image Edit Plus 2509 model. This tutorial is the product of 21 days of full R&D, costing over $800 in cloud services to find the best configurations for training. Furthermore, we have developed an amazing, ultra-easy-to-use Gradio app to use the legendary Kohya Musubi Tuner trainer with ease. You will be able to train locally on your Windows computer with GPUs with as little as 6 GB of VRAM for both LoRA and Fine-Tuning. Furthermore, I have shown how to train a character (person), a product (perfume) and a style (GTA5 artworks).
Resources
The post used in tutorial to download zip file : https://www.patreon.com/posts/qwen-trainer-app-137551634
Requirements tutorial : https://youtu.be/DrhUHnYfwC0
SwarmUI tutorial : https://youtu.be/c3gEoAyL2IE
Used Prompts
https://gist.github.com/FurkanGozukara/069523015d18a3e63d74c59257447f5b
Comparison Images Full Size
Comments (12)
ERROR: flash_attn-2.8.2-cp310-cp310-win_amd64.whl is not a supported wheel on this platform. my Python 3.12.0 CUDA 12.1
yes that is why. you need to have python 3.10.11 installed as well. it wont impact your system or other apps : https://youtu.be/DrhUHnYfwC0 follow this tutorial so you will run all apps + torch compile and it will be max speed
BTW In my experience providing detailed captions for qwen during training is more helpful that just a single unique word when you want to generate very detailed long prompts. The single phrase tends to generate garbled images the more complex the prompts. For simple prompts they operate about the same.
on the contrary i tested this and single token works better. if not working better for you there can be 2 cases. first your dataset is not consistent. second you are not properly prompting after training.
Great comparison, Flux SRPO is much better in terms of realism and also in terms of the amateur aspect of the image! Is it possible to train a Lora on your Radio app with the Flux SRPO model, or is this not yet available? Thanks for everything!
It is totally available here : https://youtu.be/nySGu12Y05k follow that tutorial. the links content configs are all updated. the downloader has flux srpo. we use same config
I love the flexibility (and the Apache2.0 license) of Qwen, but the colours and the realism are not there yet. I’m still generating with Flux.Krea. It’s still the best for me.
for realism i am preparing a new preset. you will like it
Thanks. From a quick look it does seem that the qwen images are mostly following the prompt better. Though maybe some might look slightly more real or have slighty more detail in the flux than the qwen ones. They seem to be numbered different than in the prompt. eg. prompt 5 says "werewolf hunter..." but the werewolf shows on image 4.jpg when you open that in a new window. It would be good if there could be a .zip link where we can download all the comparison images in .jpg format if that could be done (since the ones that had .png format were about 20 MB each). Maybe it would be useful if comparison info could be shown as some sort of score too, where for each set of 2 images, a score was given to one or both based on how close they matched the prompt, then a total or average score could be shown for all the test images, so it would give a value for the ai model in general. eg. for some images I assume flux spro might be a bit better (eg. the image with the flying vehicles where one looks like painted shark teeth - the bottom one - flux - seemed more like just painted on shark teeth and the qwen one looked more like an actual shark shape. So maybe flux followed that bit of the prompt a bit better). Maybe there could be scores for prompt following and another score for realism of the 2 models, based on an average of the scores for each image.
in every case Qwen wins. but for realism it is not there yet. currently i am working on improving realism with a realism lora. will share results hopefully
Oh wow! The selfie game is on point with this one! lol. It looks good!
thanks