


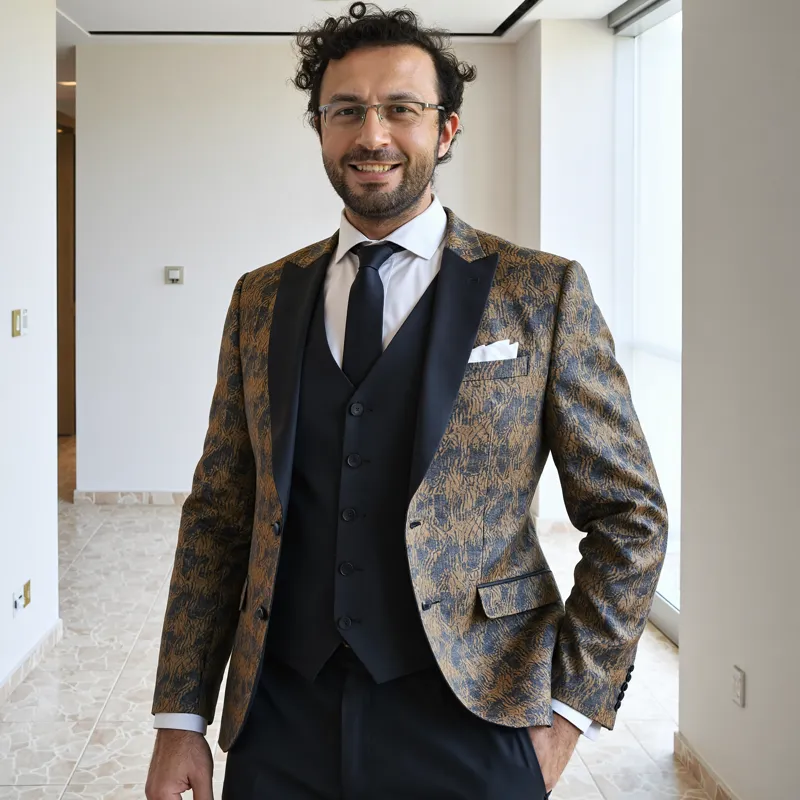


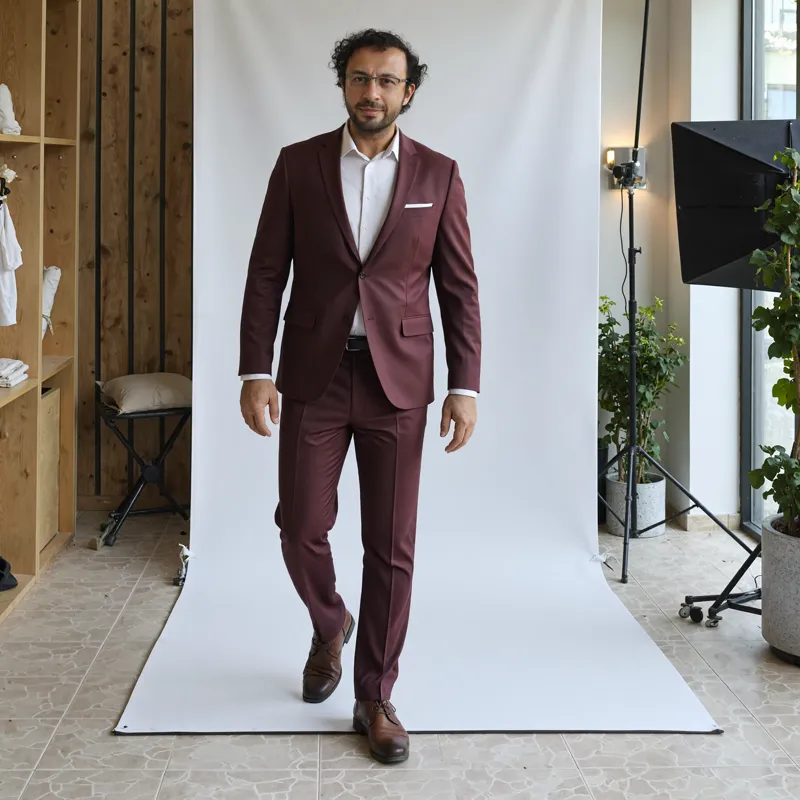


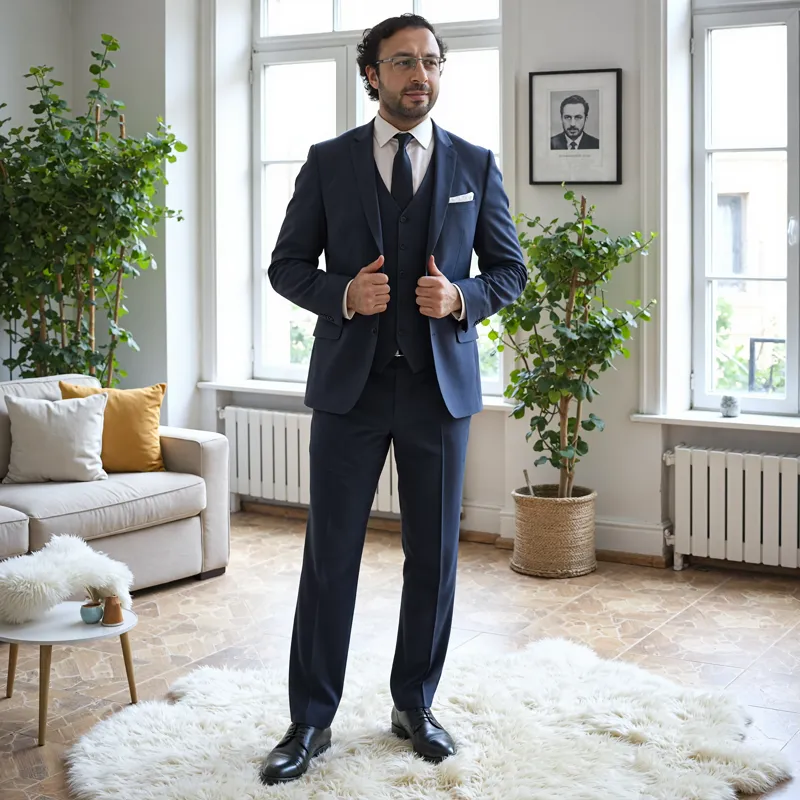


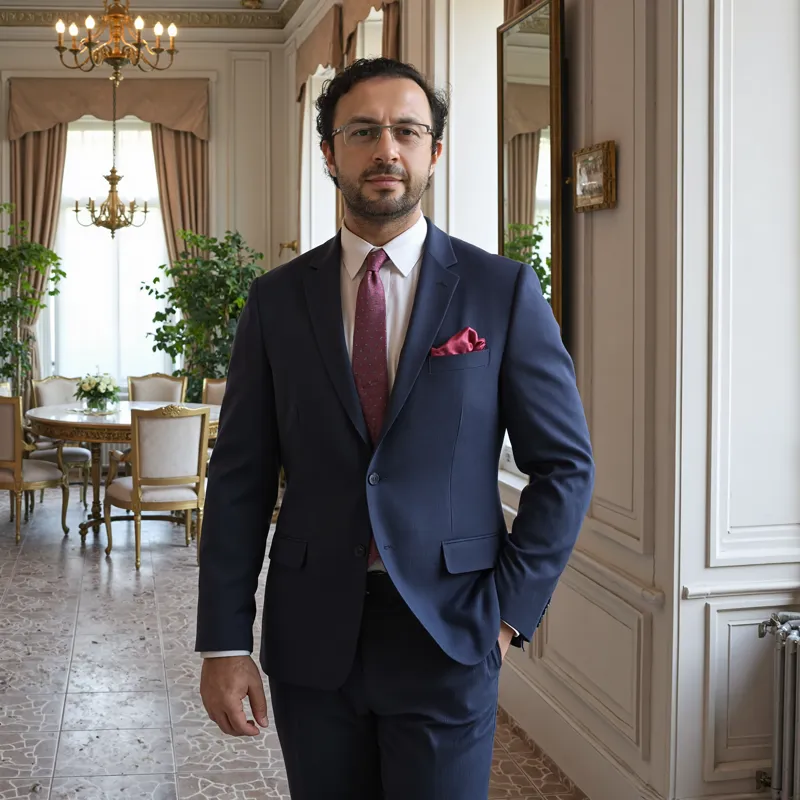

Simple prompt 2x latent upscaled FLUX - Fine Tuning / DreamBooth Images - Can be trained on as low as 6 GB GPUs - Each image 2048x2048 pixels
AI Photos of Yourself - Workflow Guide
Step 1: Initial Setup
Follow any standard FLUX Fine-Tuning / DreamBooth tutorial of your choice
You can also follow mine step by step : https://youtu.be/FvpWy1x5etM
Step 2: Data Collection
Gather high-quality photos of yourself
I used a Poco X6 Pro (mid-tier phone) with good results
Ensure good variety in poses and lighting
Step 3: Training
Use "ohwx man" as the only caption for all images
Keep it simple - no complex descriptions needed
Step 4: Testing & Optimization
Use SwarmUI grid to find the optimal checkpoint
Test different variations to find what works best
Step 5: Generation Settings
Upscale Parameters:
Scale: 2x
Refiner Control: 0.6
Model: RealESRGAN_x4plus.pth
Prompt Used:
photograph of ohwx man wearing an amazing ultra expensive suit on a luxury studio<segment:yolo-face_yolov9c.pt-1,0.7,0.5>photograph of ohwx man
Note: The model naturally generated smiling expressions since the training dataset included many smiling photos.
Note: yolo-face_yolov9c.pt used to mask face and auto inpaint face to improve distant shot face quality
Comments (10)
I have a technical question: I did follow your steps in the tutorial; however, when I used the trained dreambooth in SwarmUI, I go this error message: All available backends failed to load the model ' C:\SwarmUI\SwarmUI\Models\Stable-Diffusion\Flux\Raflux-00020.safetensors'. What is this ? I did reinstall SwarmUI or update whatever I can . Anything wrong ? I did check ae , text encorder ... I can't get any luck.
hello error is easy. you need to put models into diffusion_models folder
Can you explain the parameters you used for th yolo face model 1,0.7,0.5
it is explained here : https://github.com/mcmonkeyprojects/SwarmUI/blob/master/docs/Features/Prompt%20Syntax.md#automatic-segmentation-and-refining
Is there any benefit to using training photos with higher resolution than 1024x1024? I'm curious if there are any benefits or consequences to using higher quality training photos.
i didnt see any benefits yet . tested on human and a style.
If i train a dream-booth fine tune, do i need regularisation images when i want to appear with random people or other Loras ? Because when i trained a Lora of myself it tends to make all other people in the image to look like me. Also how many , and what kind of images i need for regularisation for a dataset of 20 images ?
sadly with flux others always almost turns into you (class bleeding). you need to inpaint their faces after image has been generated. you can use flux fill - inpainting model for that : https://youtu.be/hewDdVJEqOQ
It looks impressive, but if it's upscaling won't it be inventing details that weren't in the trained lora/dreambooth (or missing details that weren't the lora/dreambooth)? Wouldn't it be more accurate if it could train at that 2048 res (though maybe it's almost impossible with Flux/SD3.5 type models without GPUs with huge amounts of VRAM. Maybe it was Nvidia's SANA that could do about 4K but that wasn't for commercial use and I think that was the one that some images at high res looked over compressed on some image(s) on reddit and I don't know that could be trained.
sana always 1024x1024 - 4k is fake :d when last time i tried 2048 it wasnt useful for training a person or a style but you can test and compare. actually i can also compare it today with higher res training