OneTrainer Fine Tuning vs Kohya SS DreamBooth & Huge Research of OneTrainer's Masked Training
OneTrainer vs Kohya training. Moreover, comparative study of Masked Training effect. Full research.
As some of you know, I have been doing huge research on OneTrainer recently to prepare the very best Stable Diffusion training. For this purpose, I have been for days working on the effect of masked training feature of the OneTrainer.
Join discord to get help, chat, discuss and also tell me your discord username to get your special rank : SECourses Discord
So today, after doing research, I have completed more than 10 trainings and compared them. I also would like to get your ideas.
The major upcoming tutorial video not ready yet but will be on SECourses hopefully for free and I will show and explain everything including training configuration and parameters.
I used my below bad dataset for training. It is bad because it is easy to collect and i am able to compare with my previous trainings. But hopefully I will improve it and explain to everyone. The used caption during training is "ohwx man"
When doing Kohya DreamBooth training, our ground truth manually collected 5200 man regularization images dataset used with caption of "man".
When doing OneTrainer training, I added a second concept and used it as a regularization images. OneTrainer don't have DreamBooth directly so we are trying to mimic the same effect this way.
OneTrainer trained for 150 epoch.
So total trainings were 4500 steps for all of the experiments. Half of it trains regularization images and half trains training images.
If you want to see how to load preset and train with OneTrainer here a quick video : https://youtu.be/yPOadldf6bI
I have done the trainings on MassedCompute. We have prepared an amazing template on MassedCompute that comes with preinstalled and 1 click launchers for Automatic1111 Web UI, OneTrainer and Kohya currently.
Also the template has Python 3.10.13 installed and set as default. Template also includes Hugging Face upload notebook and preinstalled Jupyterlab.
Moreover, OneTrainer gave us a coupon code and thus by following the instructions in below GitHub readme file, you can use A6000 GPU on MassedCompute for only 31 cents per hour.
As a base model for training RealVis XL 4 is used. So this training made on a realistic model. Therefore, the capability of the model to generated cartoon or similar images is limited. But at realism it excels.
When testing OneTrainer masking feature I have followed the following steps.
Masks are only used for training images not for regularization images.
For masking I have used DataSet tools and masked them like below
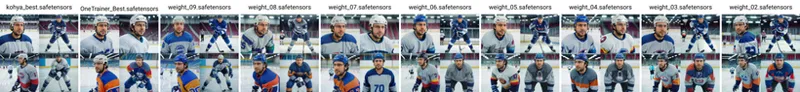
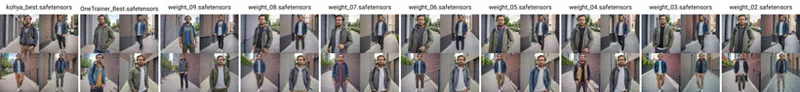
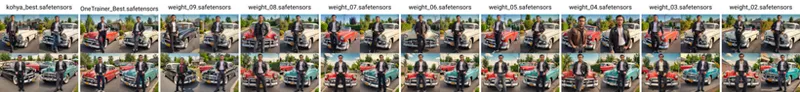
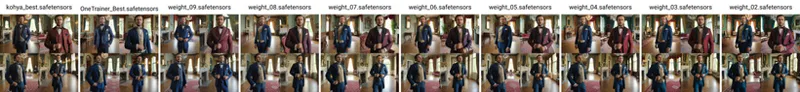
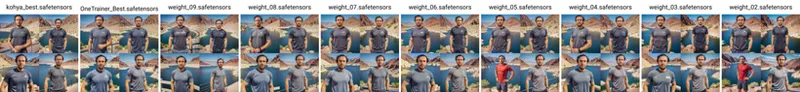
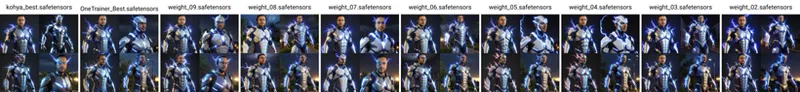
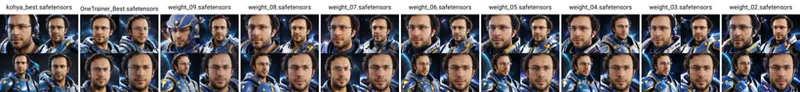
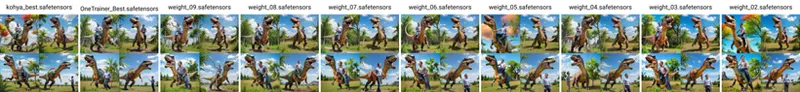
Then I have done 9 different trainings and compared Unmasked Weight. If you make Unmasked Weight 0.0 that means only the masked area which is head will be trained.
If you make Unmasked Weight 1.0, it will be same as no mask is used.
So I compared Unmasked Weight between 0.1 and 0.9. I didn't include 0.1 results since it was generating images with anatomically disproportional body.
I also want you to analyze the images and tell me which Unmasked Weight is working best? I think 0.6 or 0.7 is best. Reduces some overtraining and still able to generate accurate anatomy having images.
As you reduce the Unmasked Weight, you reduce the overtraining caused by the environment. Repeating background and clothing.
You can download all images (total 24 tests) full sizes, including their PNG info and the used full prompts here : click to download 1.5GB
Here below the images and their prompts but they are extremely downscaled by the platform.
The images are not cherry picked so many times better and perfect images can be generated easily.
You can download and see test full png info in this file : test_prompts.txt
hello! i used your settings with amazing results. i have some questions: the first one: how to fine tune a style like a new concept, i cant find anything about it. maybe the same workflow , like two diferent concepts, but for style, withh 5200 images?the second question= how to train a lora with a style. thanks!!
for style training same workflow but you should caption them properly. like ohwx style, and the caption from vision models for lora training i don't suggest it. do a fine tuning and extract lora it will be better results : https://www.patreon.com/posts/extracted-lora-108634568
鸣
鸣 陈 · May 8, 2024
Please tell me how to set the Chinese language. I don’t understand this language.
yes so close. actually most difference comes at 0.1 weight but that is really bad at anatomy
M
Mikael Svenson · April 5, 2024
Sort of missing your opinion if OneTrainer is preferred over Kohya or the other way around. The title of the post is one vs. the other. So adding a paragraph on top to summarize your opinion would be helpful. Keep up the good work on very detailed tutorials 👍
well there is no definitive answer. each one has strong and weak sides compared to each other for each use case. but onetrainer is certainly stronger for lower VRAM usage and also masked training is so easy
P
Pew · April 3, 2024
Furkan, I'm a fan of your work and thank you for contributing so much in terms of not only helping and educating, though doing so backed by extensive testing and research. I'm always impressed by now detailed you are when bringing to the forefront any claim or disposition. Can you please answer this question? I've not used Runpod before. and I do, to test a serious of models simultaneously, is it suggested to secure one Runpod instance with multiple GPUs or multiple pods each with a single GPU? Technically speaking, I don't know what's possible, though how do you train or test multiple models simultaneously on that platform?
multiple gpu within 1 pod. that way you can quickly use each gpu to do seperate trainings at the same time. i can give private lecture about this if you wish. i did such training there