



How to Setup Unrestricted local AI Image Editor using ComfyUI
This goes with my video tutorial on how to setup unrestricted local AI image editor / generator using ComfyUI. This method has as good generative and editing capabilities as most of the lobotimized AI image generators available, such as gemini, chatGPT, copilot ..etc, minus the lobotomy part (it does what you tell it).
I've had enough of those restricted versions, they can't do anything anymore! they trip over their own shadow! As they say: if you want something done right, do it yourself! so once again, i DID do it myself and here's how. This is not a full tutorial as this is extension to my video tutorial and includes all the commands so you can easily copy paste them.
Commands need to be ran in admin powershell and you need to copy them as one single line, if there are line-breaks, it won't work. If they copy wrong, then paste them into notepad++ and remove hidden line breaks or give this entire post to AI and ask it to extract powershell commands and provide them as single lines.
Based on which models you're going to use, you'll need at least 50gb of space.
NOTE: CUDA-capable GPU is highly recommended as without it, process will be slow. I'm using RTX 3080 and 1080p edits take 1-3 minutes. here's a comparison table how long same image would take on different hardware:
RTX 3080: 1–3 minutes
RTX 5090: 0.5–1.5 minutes
RTX 4090: 0.5–2 minutes
RTX 4080: 1–2.5 minutes
RTX 4070 Ti Super: 1.5–3.5 minutes
RTX 3060 12GB: 4–8 minutes
Intel Arc B580 12GB: 2–5 minutes
Intel Arc Pro B70 32GB: 2–4 minutes
High-end AMD GPU: 2–6 minutes
Powerful Intel i9 CPU only: 30–90+ minutes
Examples
Before:
Edit 1:
Edit 2:
Edit 3:
Edit 4: 16:9 aspect ratio
image is fully expanded from vertical to 16:9 aspect ratio, sides of image are fully added by AI, i made this specifically to serve as thumb for this post.
Original (made by gemini):
Edit 1:
'e' is bit crooked as that font is custom made by gemini and it didn't know how lower-case chars look like, for better results you have to provide full fonts as reference image.
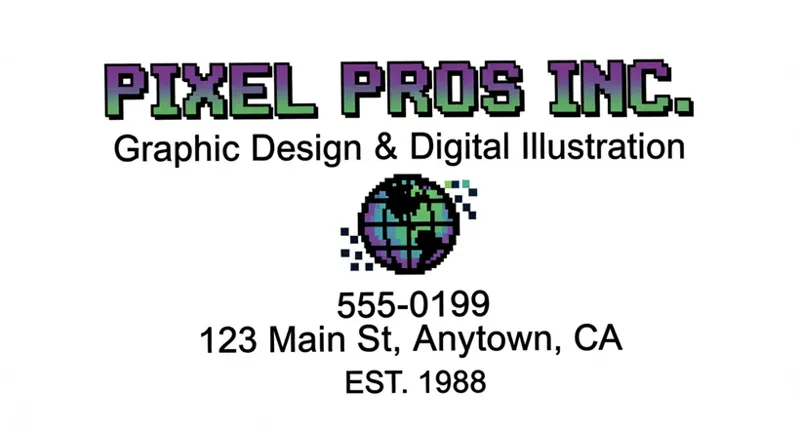
Extract & Enhance:
this is fully extracted and enhanced image from original. so you can easily turn your old graphics into fresh printable copies! remove those coffee stains!
Install python
Install in default folder:
winget install --exact --id Python.Python.3.11 --source winget --accept-source-agreements --accept-package-agreements
Install on another drive or specific folder:
New-Item -ItemType Directory -Force -Path 'A:\AI\Python311' | Out-Null; winget install --exact --id Python.Python.3.11 --source winget --override "/quiet InstallAllUsers=0 TargetDir=A:\AI\Python311 PrependPath=1 Include_test=0" --accept-source-agreements --accept-package-agreements
Set ComfyUI Root folder:
$Root = Join-Path $env:USERPROFILE 'ComfyUI'
Optionally use custom path (edit as needed):
$Root = 'A:\AI\ComfyUI'
Download & extract ComfyUI
$ErrorActionPreference='Stop'; $Zip="$env:TEMP\ComfyUI-master.zip"; $Stage="$env:TEMP\ComfyUI-stage-$PID"; if(Test-Path $Root){throw "Destination already exists: $Root"}; New-Item -ItemType Directory -Force -Path (Split-Path -Parent $Root) | Out-Null; Remove-Item $Zip,$Stage -Recurse -Force -ErrorAction SilentlyContinue; curl.exe -L --fail --retry 5 --retry-delay 2 -o $Zip 'https://github.com/Comfy-Org/ComfyUI/archive/refs/heads/master.zip'; if($LASTEXITCODE -ne 0){throw 'ComfyUI download failed'}; Add-Type -AssemblyName System.IO.Compression.FileSystem; $z=[System.IO.Compression.ZipFile]::OpenRead($Zip); try{if($z.Entries.Count -eq 0){throw 'Invalid ZIP'}}finally{$z.Dispose()}; Expand-Archive -LiteralPath $Zip -DestinationPath $Stage -Force; $Source=Join-Path $Stage 'ComfyUI-master'; if(!(Test-Path $Source)){throw 'ComfyUI source folder was not found'}; Move-Item $Source $Root; Write-Host "Installed to $Root"
Install Python dependencies
py -3.11 -m pip install --upgrade pip
Install PyTorch (requires CUDA GPU)
py -3.11 -m pip install torch==2.10.0+cu130 torchvision==0.25.0+cu130 torchaudio==2.10.0+cu130 --index-url https://download.pytorch.org/whl/cu130
Optional CPU-only version (if no CUDA GPU - EXTREMELY SLOW)
py -3.11 -m pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cpu
Install ComfyUI dependencies
py -3.11 -m pip install -r "$Root\requirements.txt"
Create model folders
New-Item -ItemType Directory -Force -Path "$Root\models\diffusion_models","$Root\models\text_encoders","$Root\models\vae","$Root\models\loras","$Root\user\default\workflows" | Out-Null
Model + Workflow Set 1 (best for Text/Graphics editing)
Qwen image edit 2511 - 20.5gb:
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\diffusion_models\qwen_image_edit_2511_fp8mixed.safetensors" "https://huggingface.co/Comfy-Org/Qwen-Image-Edit_ComfyUI/resolve/main/split_files/diffusion_models/qwen_image_edit_2511_fp8mixed.safetensors"
Qwen text encoder - 8.7gb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\text_encoders\qwen_2.5_vl_7b_fp8_scaled.safetensors" "https://huggingface.co/Comfy-Org/HunyuanVideo_1.5_repackaged/resolve/main/split_files/text_encoders/qwen_2.5_vl_7b_fp8_scaled.safetensors"
VAE - 254mb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\vae\qwen_image_vae.safetensors" "https://huggingface.co/Comfy-Org/Qwen-Image_ComfyUI/resolve/main/split_files/vae/qwen_image_vae.safetensors"
Lightning LoRA - 810mb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\loras\Qwen-Image-Edit-2511-Lightning-4steps-V1.0-bf16.safetensors" "https://huggingface.co/lightx2v/Qwen-Image-Edit-2511-Lightning/resolve/main/Qwen-Image-Edit-2511-Lightning-4steps-V1.0-bf16.safetensors"
Workflow file (.json)
curl.exe -L --fail --retry 5 -o "$Root\user\default\workflows\Qwen-Image-Edit-2511-Graphics.json" "https://raw.githubusercontent.com/Comfy-Org/workflow_templates/main/templates/image_qwen_image_edit_2511.json"
Fast mode: enable Lightning, use 4 steps and CFG 1.0.
Quality comparison: disable Lightning, try 25–40 steps and CFG 4.0.
Select the FP8 model and other downloaded files in their respective model loaders.
Model + Workflow Set 2 (best for humans / nature / animals)
Qwen Image 2.1 Uncensored - 6.63gb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\diffusion_models\qwen-image-2.1-UC-fp8.safetensors" "https://huggingface.co/abenzerps/Qwen-Image-2.1-Uncensored-Quantized/resolve/main/qwen-image-2.1-UC-fp8.safetensors"
Qwen image text encoder - 9.35gb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\text_encoders\qwen3vl_8b_int8_convrot.safetensors" "https://huggingface.co/abenzerps/Qwen-Image-2.1-Uncensored-Quantized/resolve/main/text_encoders/qwen3vl_8b_int8_convrot.safetensors"
VAE - 676mb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\vae\qwen_image_2.1_vae_bf16.safetensors" "https://huggingface.co/abenzerps/Qwen-Image-2.1-Uncensored-Quantized/resolve/main/vae/qwen_image_2.1_vae_bf16.safetensors"
Workflow file (.json)
curl.exe -L --fail --retry 5 -o "$Root\user\default\workflows\Qwen-Image-2.1-Human-Edit.json" "https://raw.githubusercontent.com/Comfy-Org/workflow_templates/main/templates/image_qwen_image_2_1_image_edit.json"
Optional model for prompt refinement and thinking - 8.8gb
curl.exe -L --fail --retry 5 --retry-delay 2 -o "$Root\models\text_encoders\qwen3.5_9b_qwen_image_2.1_pe_i2i.int8_convrot.safetensors" "https://huggingface.co/Comfy-Org/Qwen-Image-2.1/resolve/main/text_encoders/qwen3.5_9b_qwen_image_2.1_pe_i2i.int8_convrot.safetensors"
once downloaded, choose "qwen3.5_9b_qwen_image_2.1_pe_i2i.int8_convrot.safetensors" in the "PE_model" field.
Create launchers (.bat files)
create empty .bat file and open it with notepad++
then paste one of those inside it
NVIDIA CUDA launcher
@echo off
cd /d "%~dp0"
py -3.11 main.py --disable-pinned-memory --auto-launch
pause
CPU-only launcher
@echo off
cd /d "%~dp0"
py -3.11 main.py --cpu --auto-launch
pause
save the file
run the .bat
I think that's all, if you have any questions or errors, i suggest just ask Claude or DeepSeek, chatGPT is actually quite good aswell, but i don't like their NAG about "get premium get premium GEEEET PREMIUM" .. about about NO! stop nagging in my face!
DeepSeek has no paid plan btw, no nag, no ads and it has quite amazing problem solving. Claude is still the best AI so far, its problem solving is amazing, but for something this simple, DeepSeek will be perfect!
I also have locally hosted DeepSeek, but due lack of VRAM, it's quite slow :( If i had 32gb VRAM i could run much better LLMs, but that's for next time! If i had more supporters .. i could get GPU with more VRAM so i can make better tutorials with better models.
If you found this useful, consider supporting my hard work and effort. It took me days setting this up and testing different models and parameters.