
Generate Photos Of Yourself In Different Cities & Different Fancy Suits With SDXL DreamBooth Training For Free
Join discord and tell me your discord username to get a special rank : SECourses Discord
To train this model I have used Stable Diffusion XL (SDXL) 1.0 Base model. I still find base model best for realism.
I used the configuration I shared here currently. It has been discovered after 120 different full trainings experimentation : https://www.patreon.com/posts/very-best-for-of-89213064
Hopefully I will make a full big tutorial of DreamBooth training and show all the settings.
For training Kohya SS GUI is used. If you don’t know how to install and use Kohya SS GUI here the tutorial you need > https://youtu.be/sBFGitIvD2A
And here is the tutorial that shows how to use shared configuration both on Windows and RunPod > https://www.youtube.com/watch?v=EEV8RPohsbw
<figure>
</figure>
If you are not my Patreon supporter currently I have full public tutorial for LoRA training of SDXL that requires 12 GB VRAM > https://youtu.be/sBFGitIvD2A
If you don’t have a strong GPU and PC you can use Free Kaggle notebook for SDXL DreamBooth training > https://youtu.be/16-b1AjvyBE
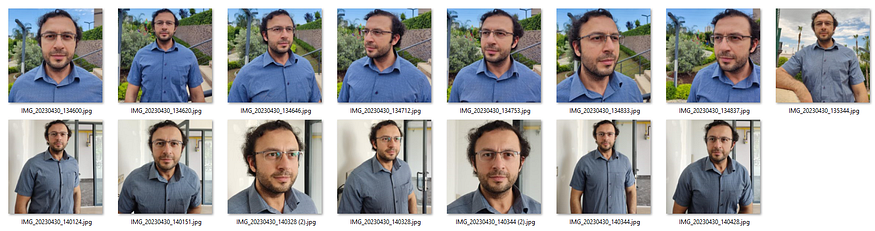
So I used the below images as training images dataset.
This training dataset is at best medium quality because it has repeating backgrounds, repeating clothing and missing fully body pose. All these causes overtraining and lesser generalization.
Then for training configuration I did the following.
When training with regularization images, I did 1 epoch and 150 repeating. So more regularization images are used. And saved checkpoints at every 30 epochs. To make it that way calculate the number of steps you need to save. It is easy. 15 * 30 * 2 + 1
The images are generated from epoch 150 so it is a little bit overtrained.
I have used ultra high quality manually picked Unsplash real images having man dataset as regularization images dataset. This means they were ground truth regularization images like how Stable Diffusion was initially trained.
You can download dataset from > https://www.patreon.com/posts/massive-4k-woman-87700469
5200 images for both man and woman. Perfect quality cropped and resized to many common resolutions.
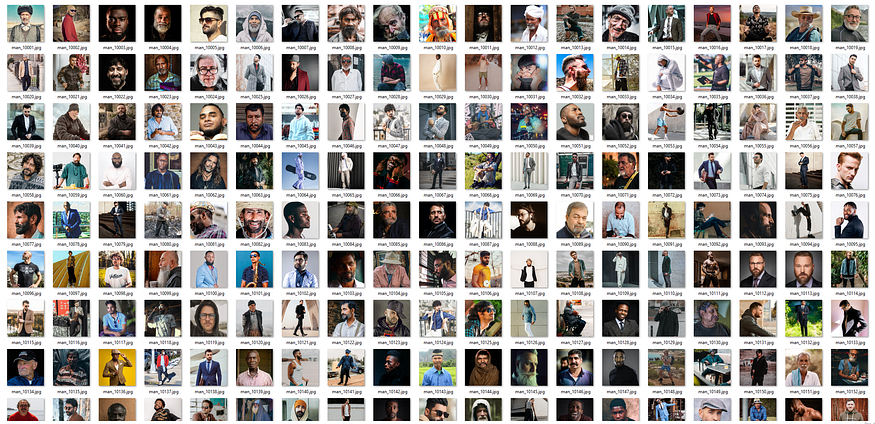
All training images and reg images were 1024x1024 pixels.
Used dynamic prompting so multiple color suits are generated.
Used prompts are as below.
Positive
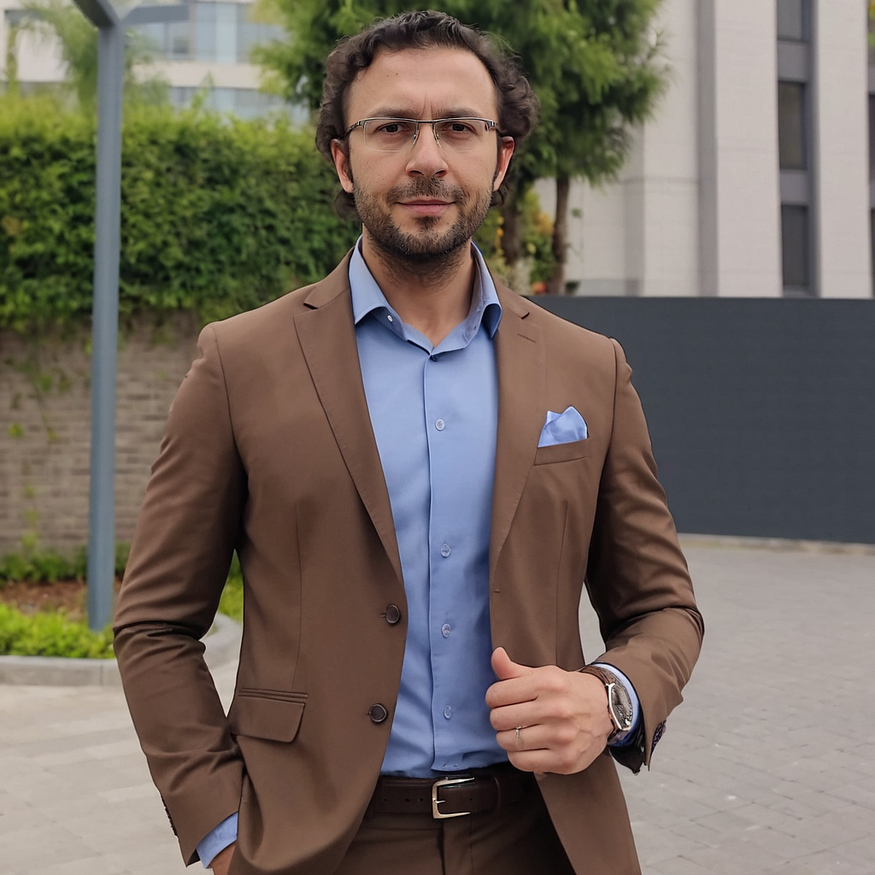
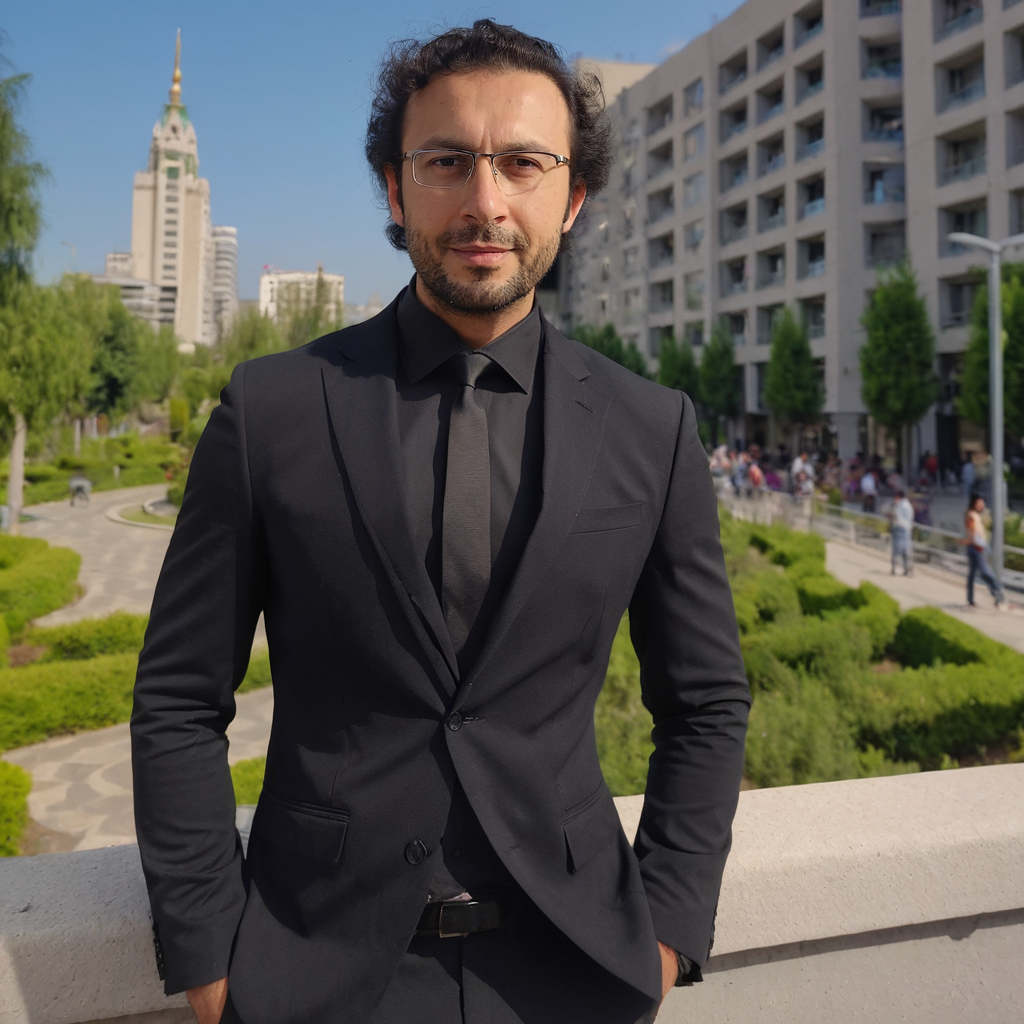
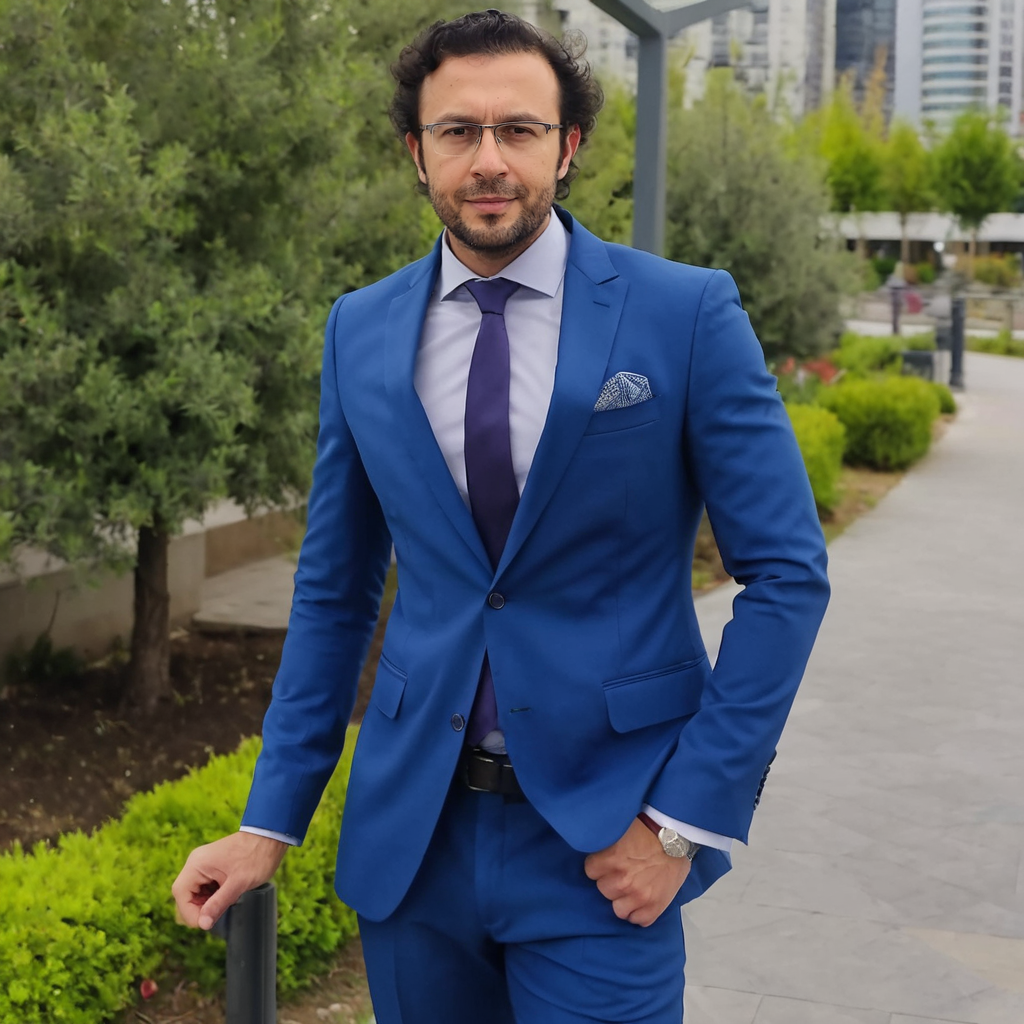
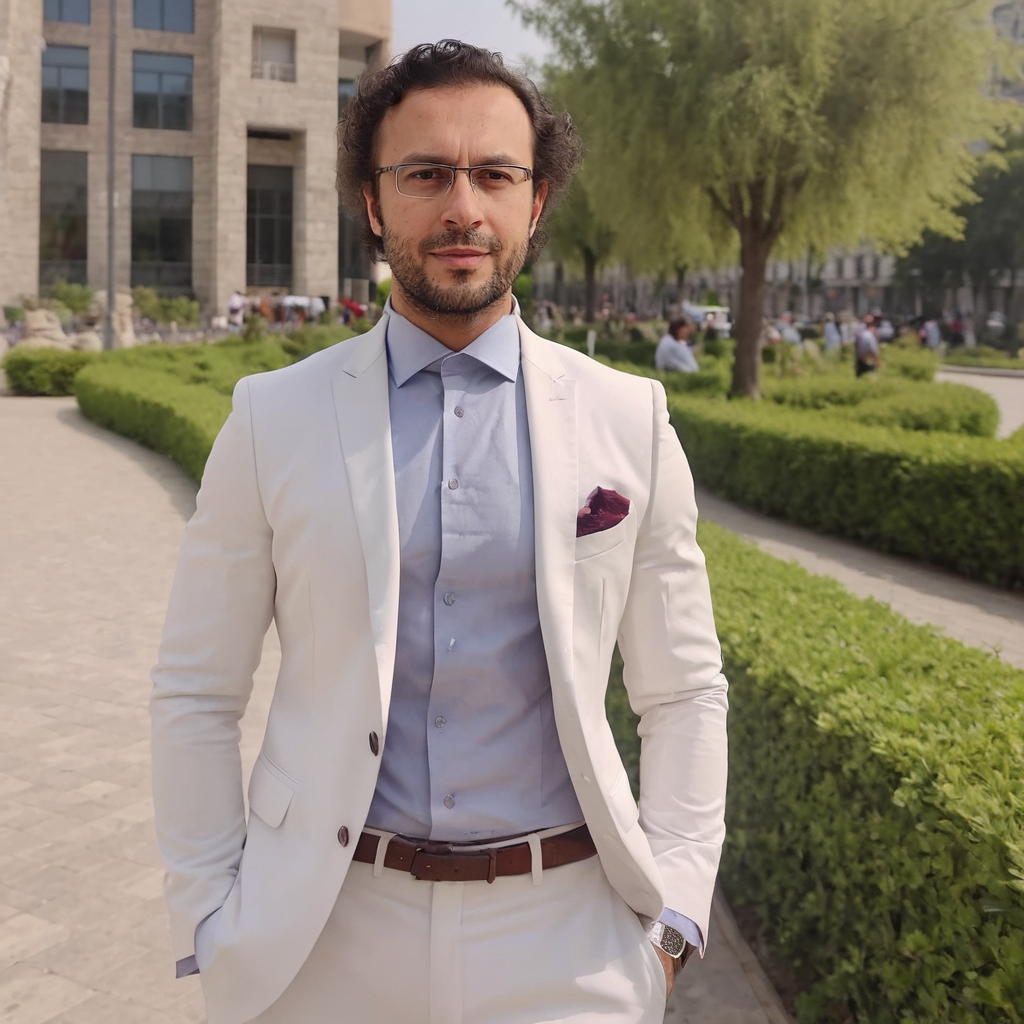
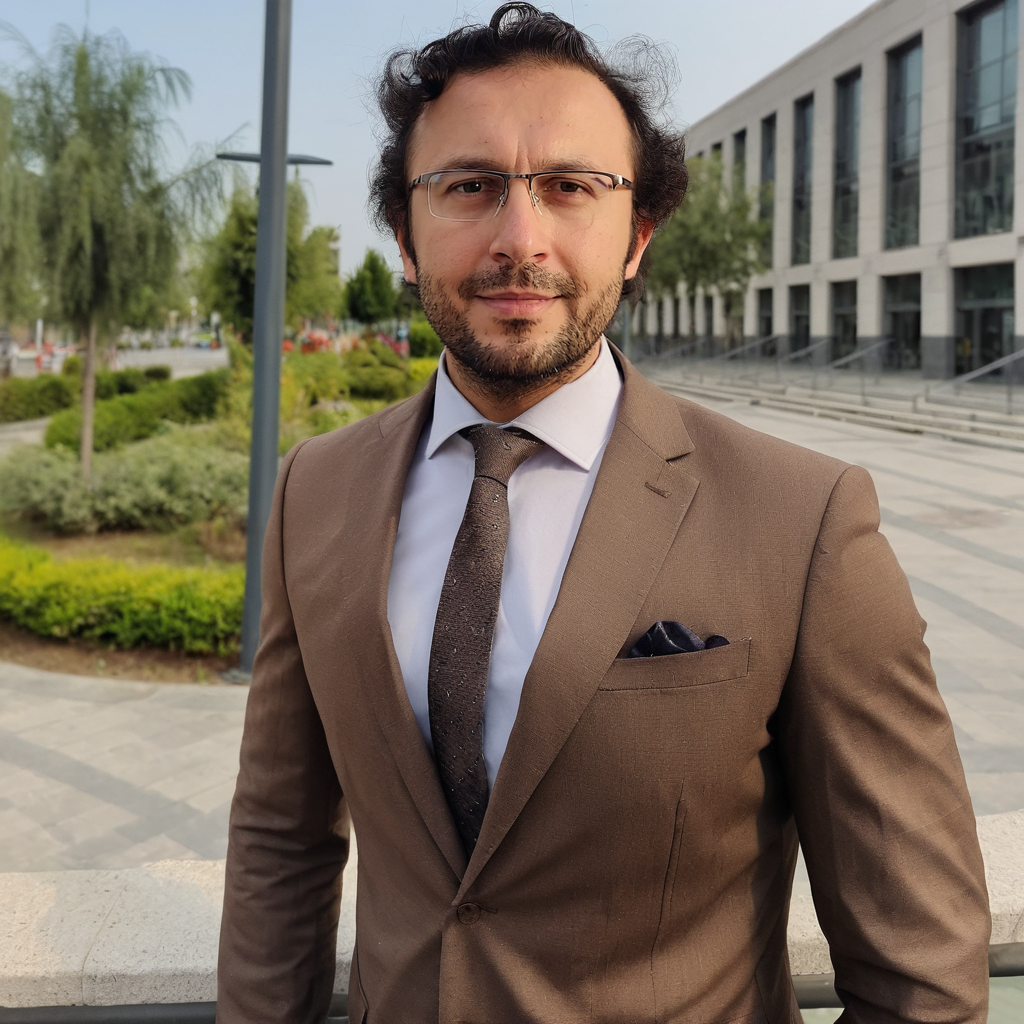
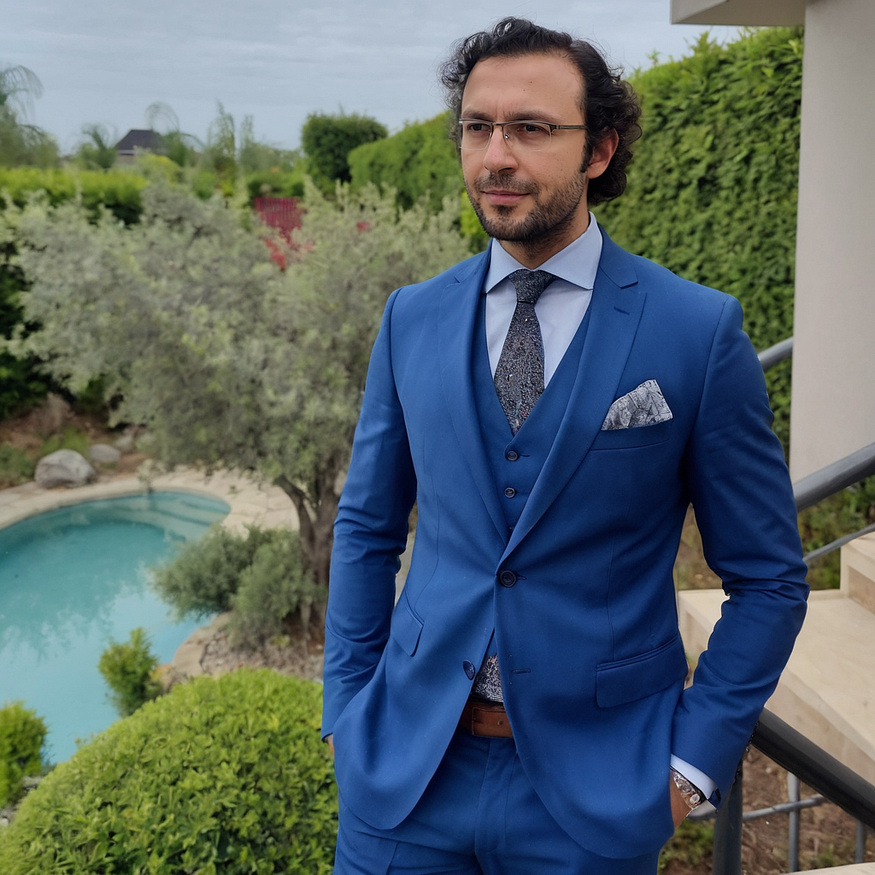
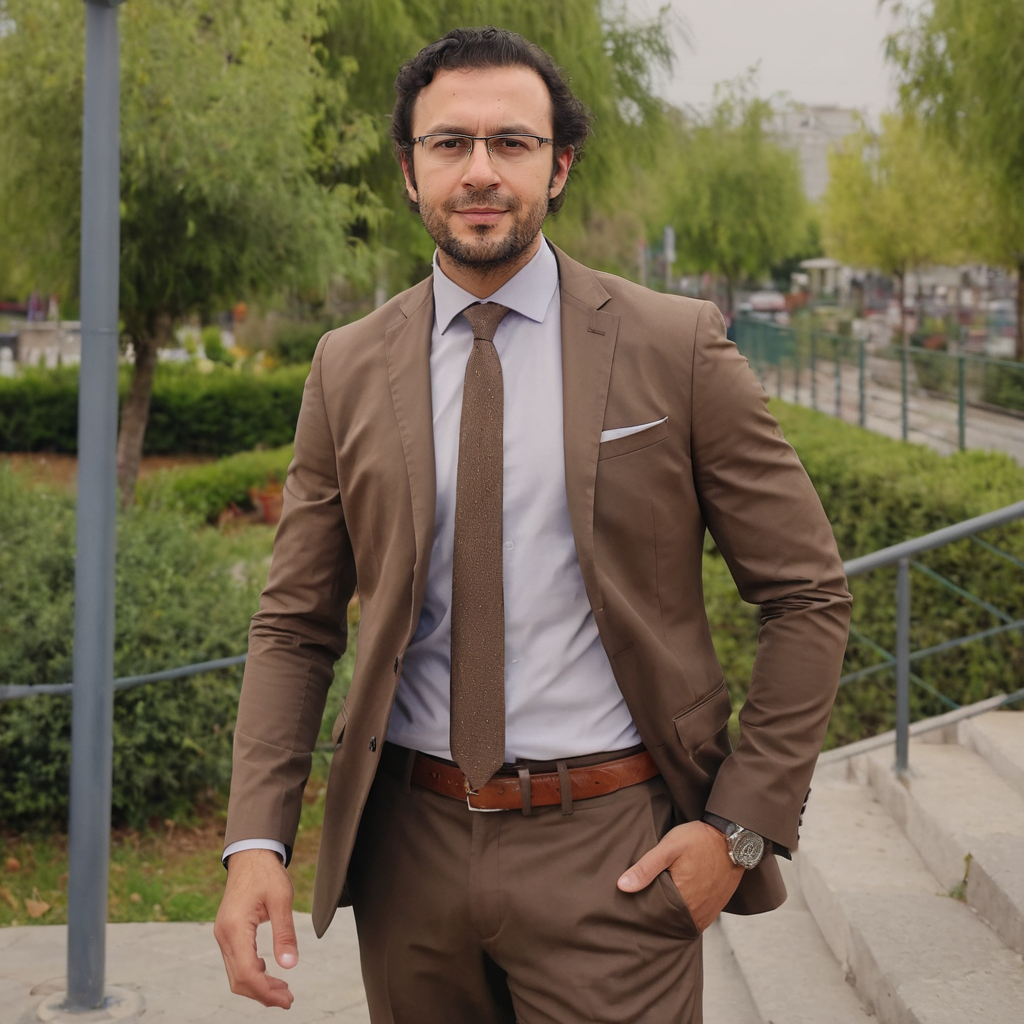
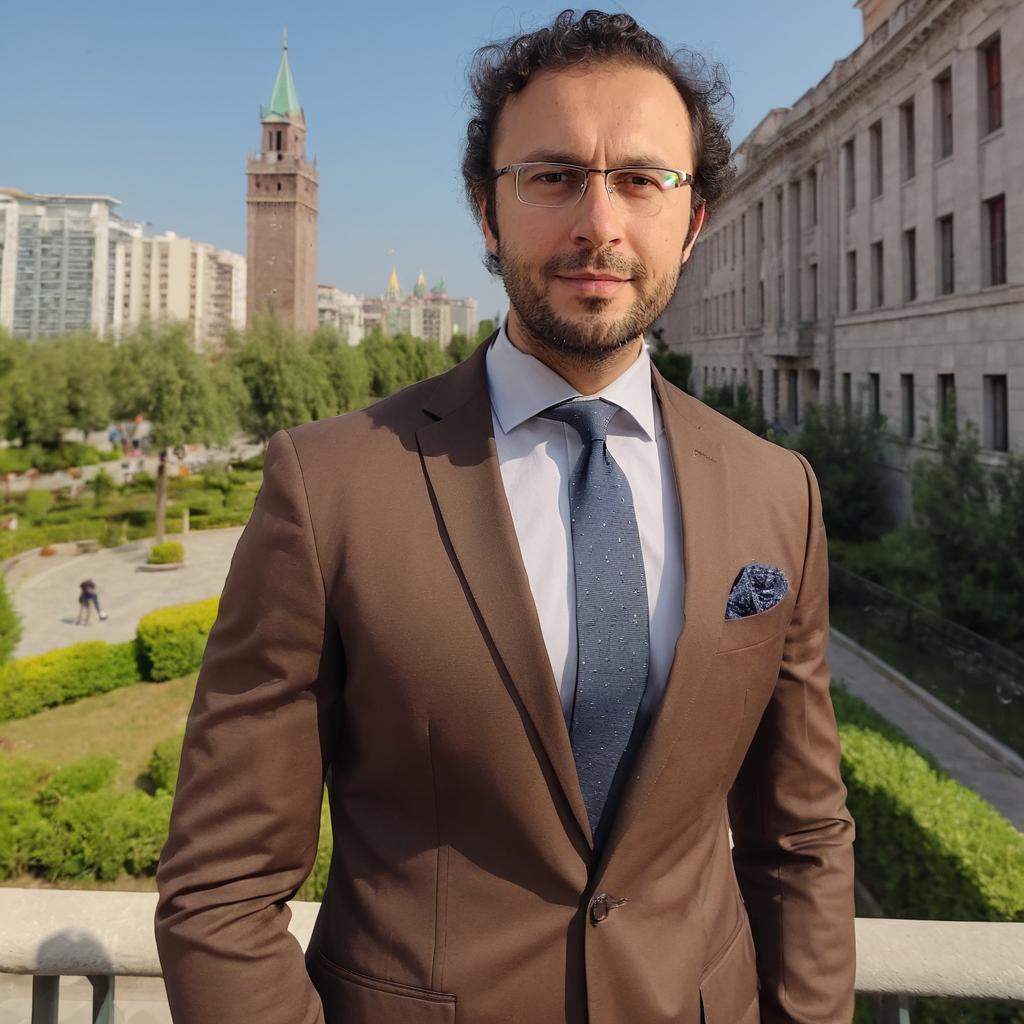
ohwx:0.98 man slightly smiling wearing and wearing an expensive {red|blue|white|black|brown|gold} suit , photoshoot in a sunny day in a city , hd, hdr, uhd, 2k, 4k, 8k
Negative
sunglasses, illustration, 3d, 2d, painting, cartoons, sketch, squinting eyes, blurry
In the after detailer (ADetailer) the following settings are used.
Prompt
photo of ohwx man slightly smiling
0.7 denoiose and 29 steps. Rest are default.
Here below full png info
parameters
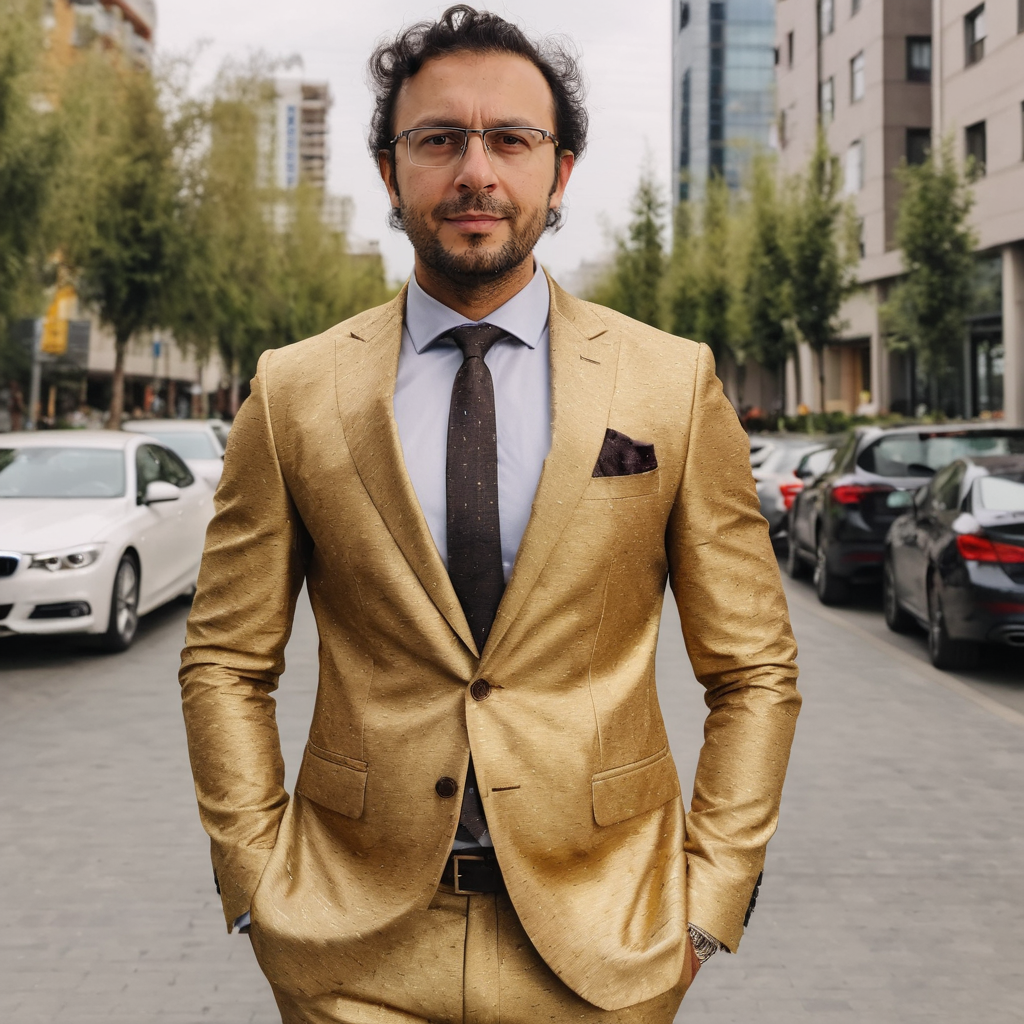
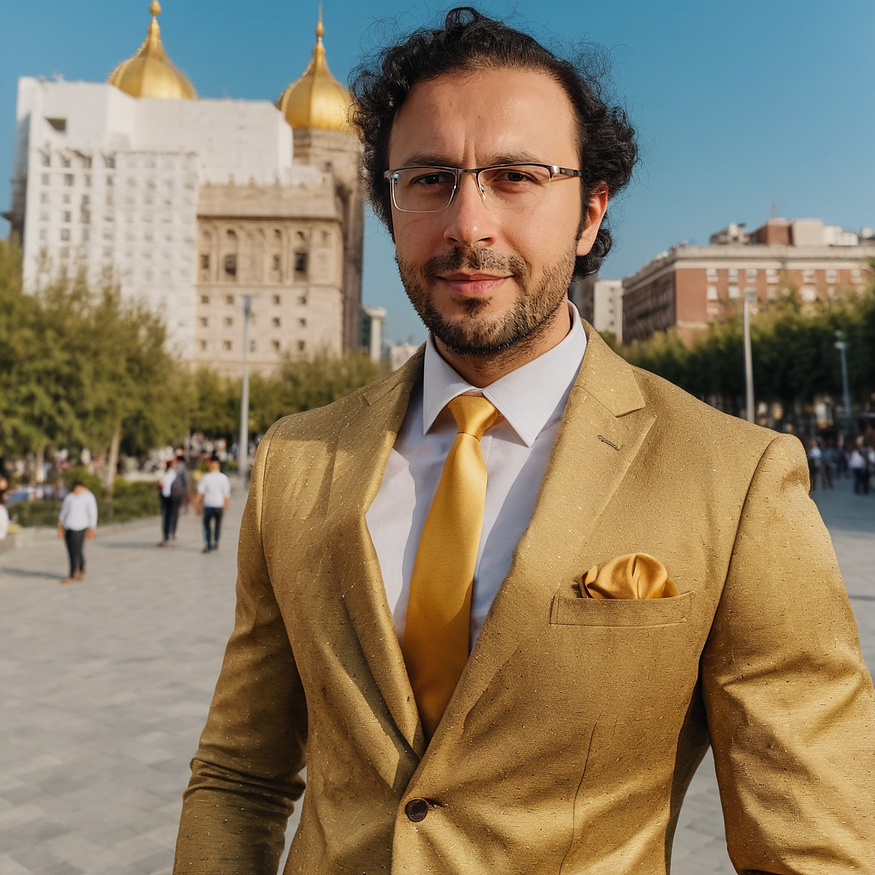
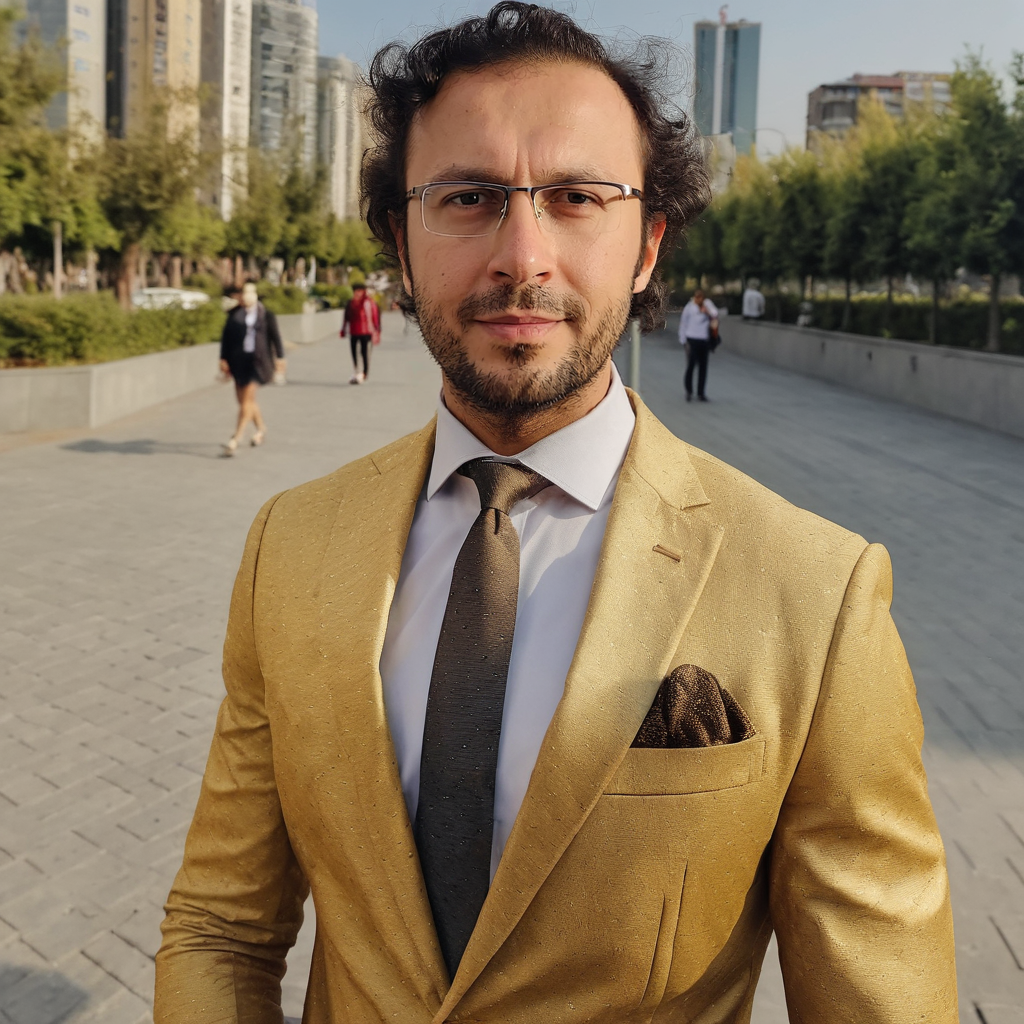
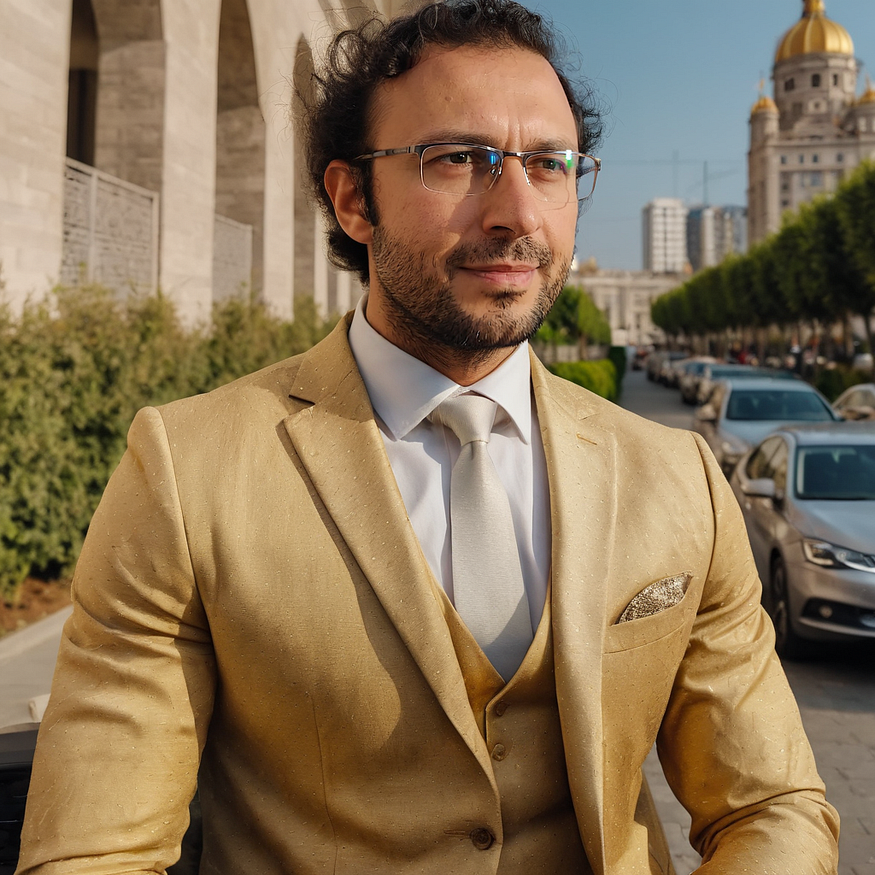
ohwx:0.98 man slightly smiling wearing and wearing an expensive gold suit , photoshoot in a sunny day in a city , hd, hdr, uhd, 2k, 4k, 8k,
Negative prompt: sunglasses, illustration, 3d, 2d, painting, cartoons, sketch, squinting eyes, blurry
Steps: 20, Sampler: DPM++ 2M SDE Karras, CFG scale: 7, Seed: 744692608, Size: 1024x1024, Model hash: eef545047f, Model: me15img_150repeat, ADetailer model: face_yolov8n.pt, ADetailer prompt: photo of ohwx man slightly smiling, ADetailer confidence: 0.3, ADetailer mask only top k largest: 1, ADetailer dilate erode: 4, ADetailer mask blur: 4, ADetailer denoising strength: 0.7, ADetailer inpaint only masked: True, ADetailer inpaint padding: 32, ADetailer use separate steps: True, ADetailer steps: 29, ADetailer version: 23.11.1, Version: v1.7.0-133-gde03882d
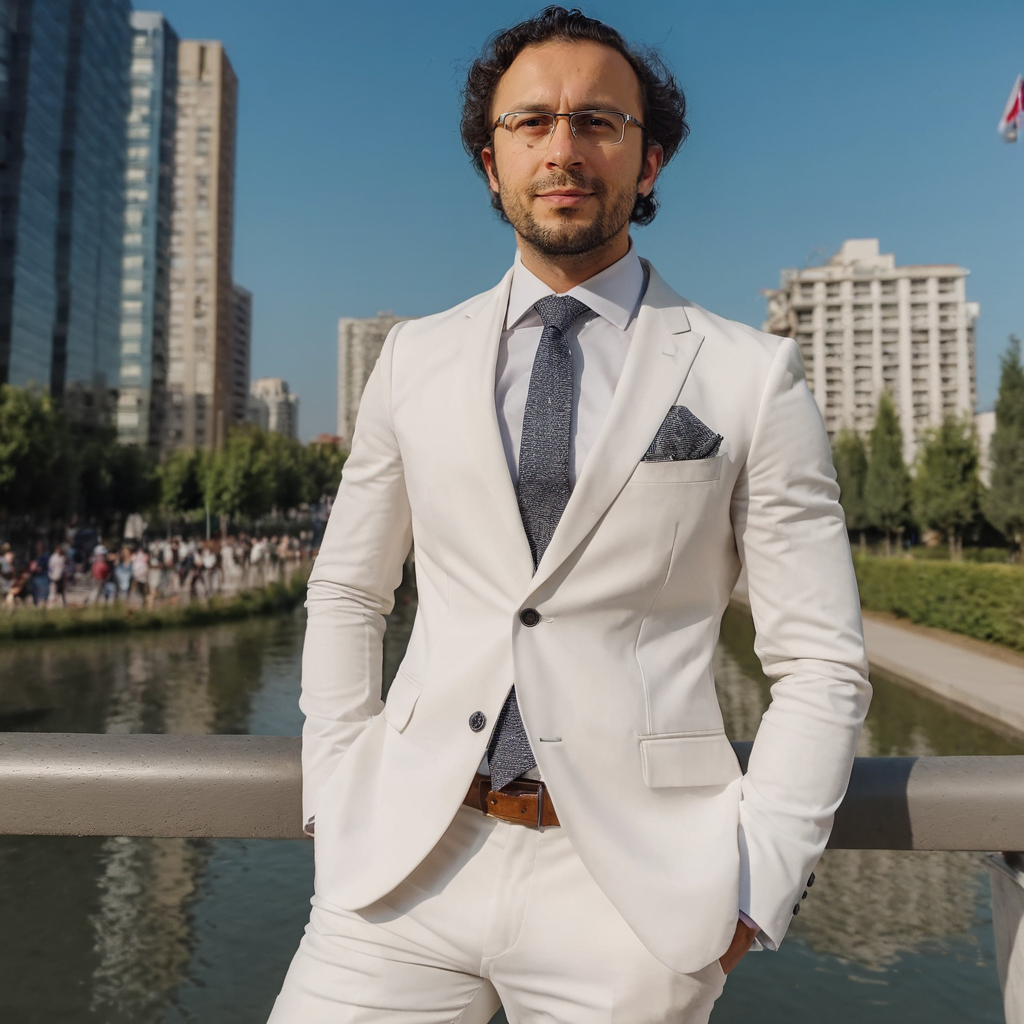
And here the results.
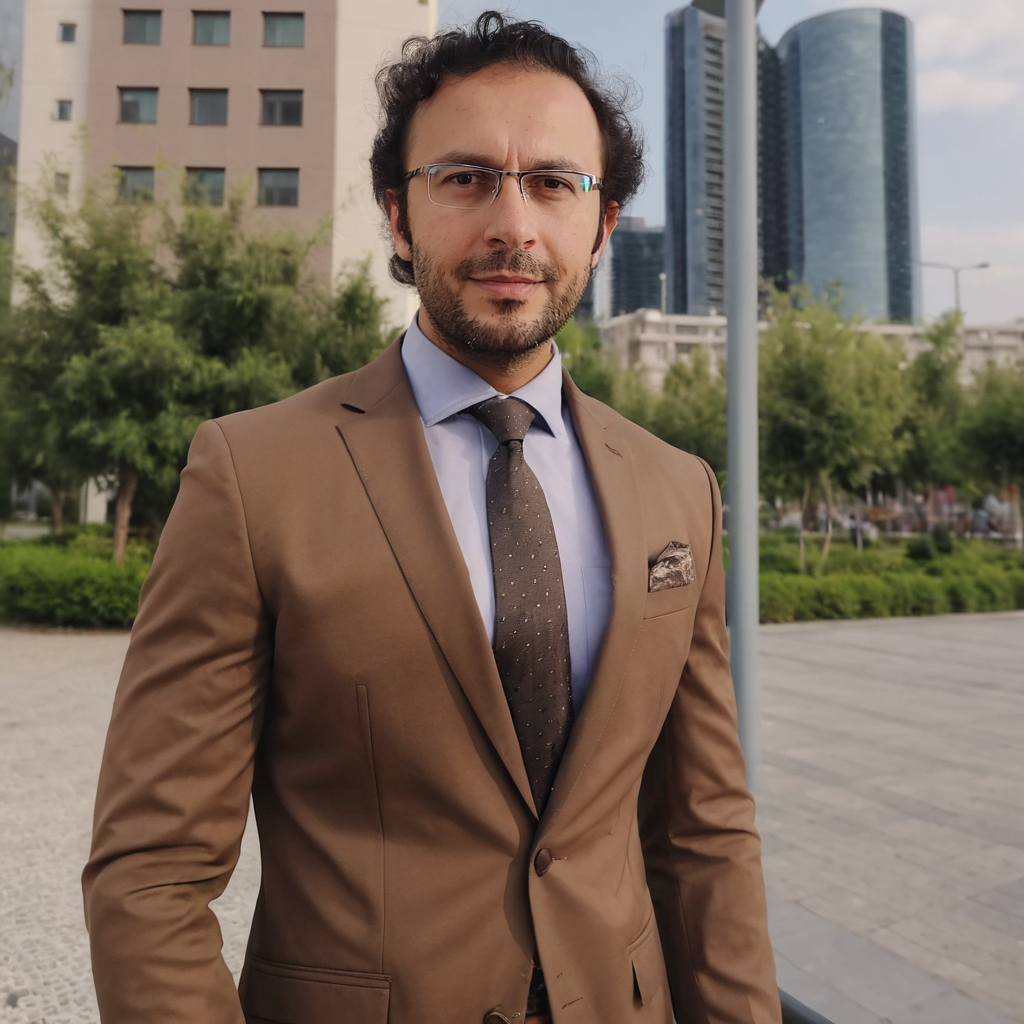
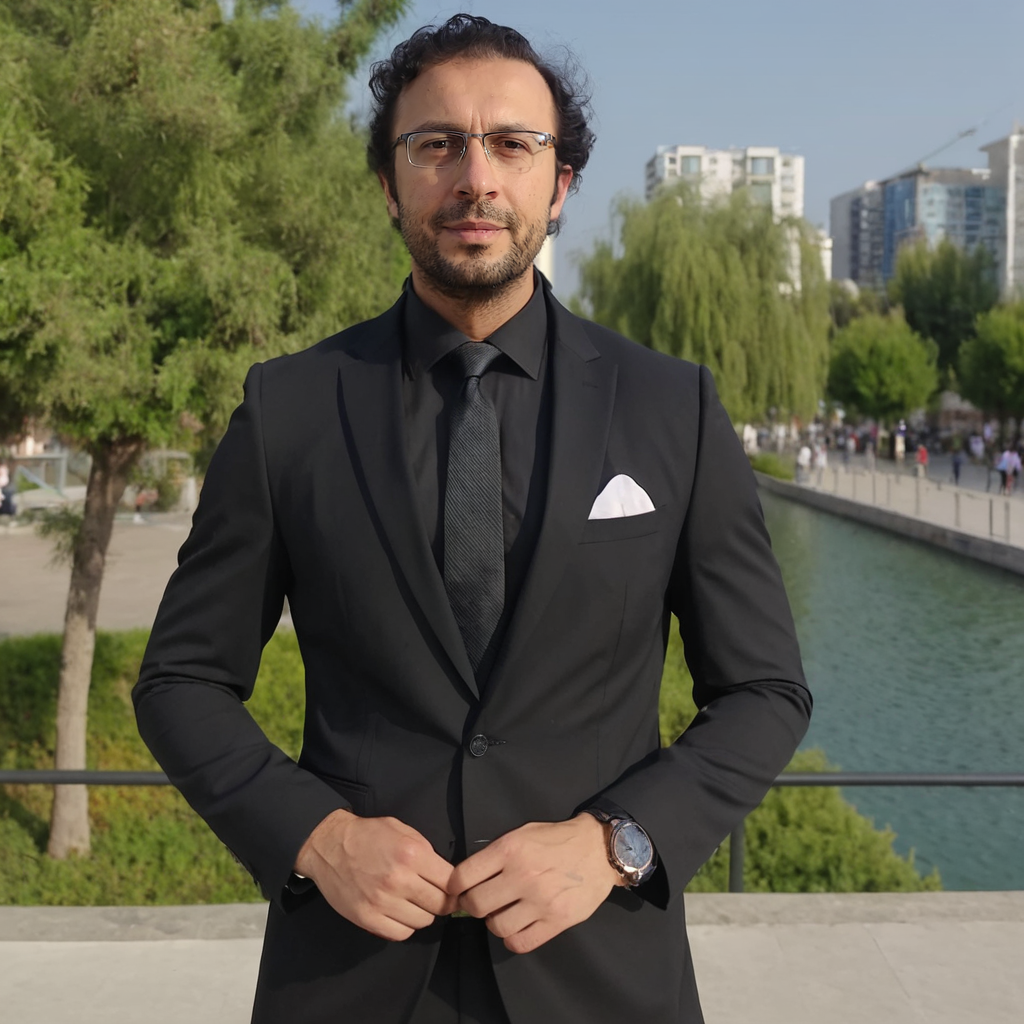
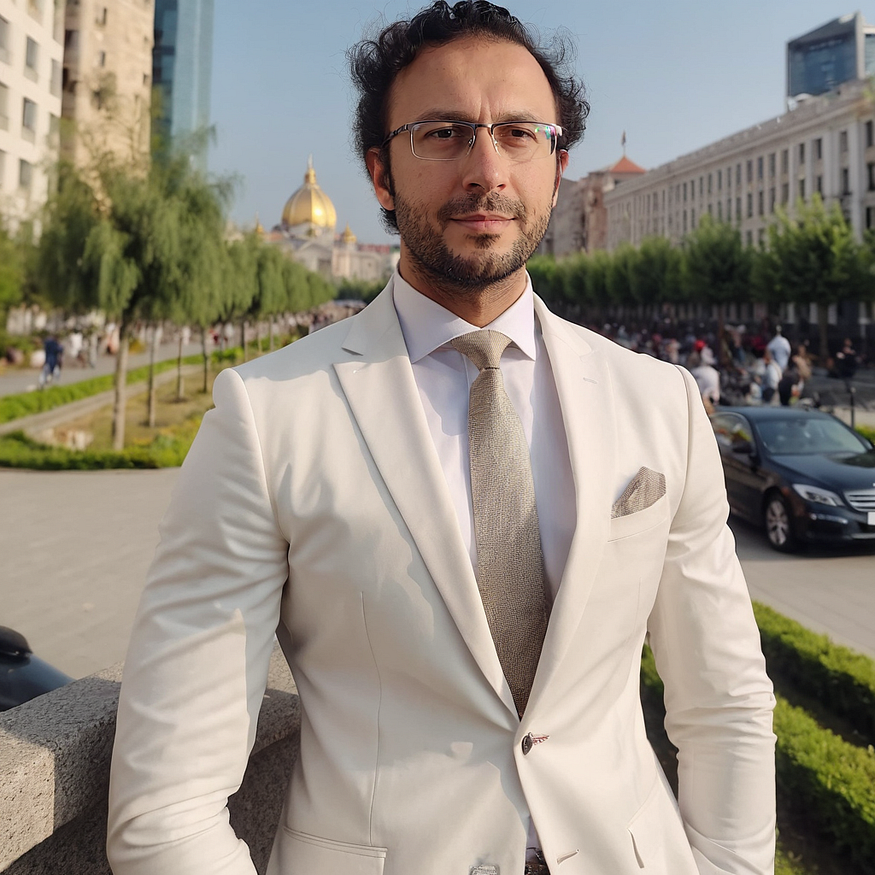
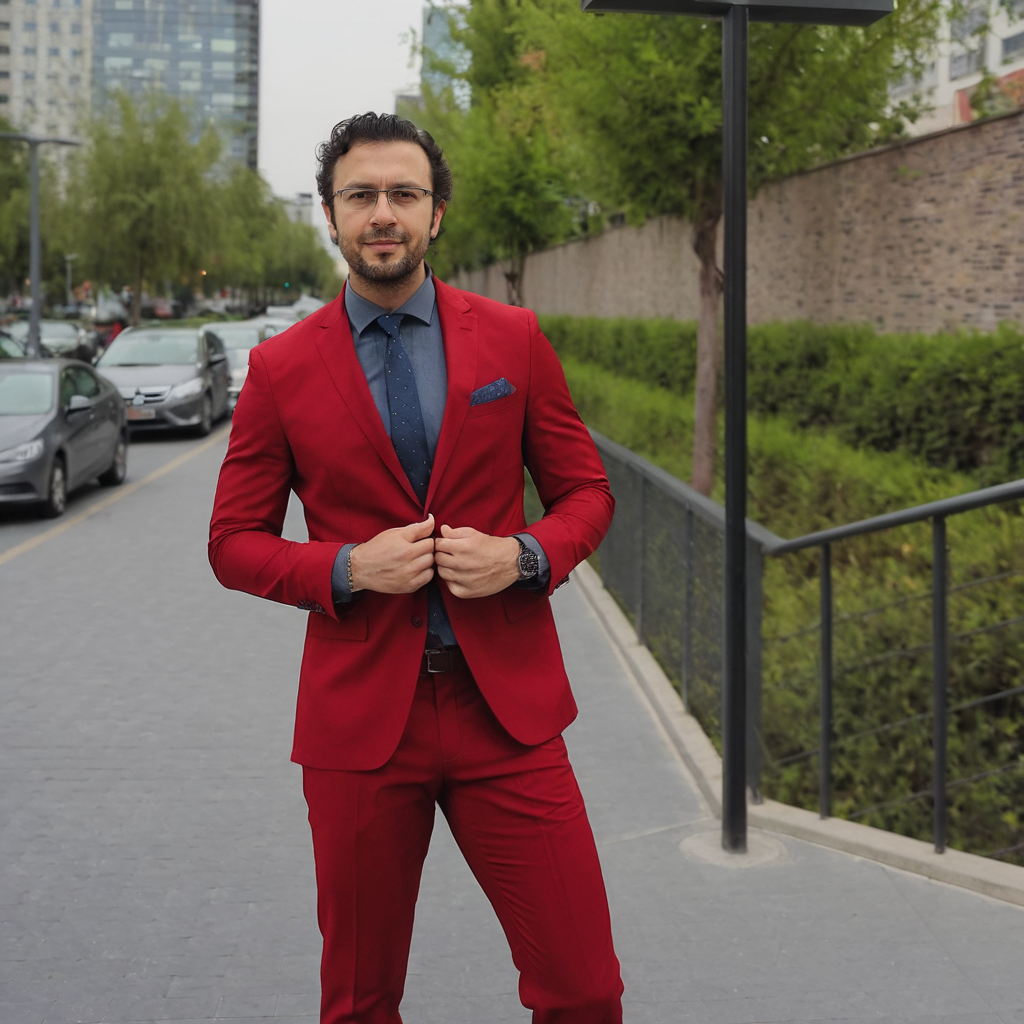



Comments (16)
I recently came across this tutorial and found it incredibly helpful. I was able to generate images of myself with similar likeness but I haven't been able to match your level of realism. I was wondering if you might be available for a one-on-one session to help me better understand this and troubleshoot?
sure i am giving private lectures. for companies 250$ per hour and for individuals 125$ per hour. you can private message me
I have got one more question that would like to ask you. I followed all above steps but the lora model that I trained vs webui results are so very different and so unrelated (i can see completely different person from webui results). I guess I couldn't call properly my lora models from Lora tab for using my webUI prompt. As you mentioned in the positive prompt, I called the ohwx:0.98 man keywords with rest of the positive prompt but looks like it didn't trigger anything from my lora files. Apart from this, do I need to add one of the Lora models to the prompt and call it as a checkpoint via Prompt S/R? I mean after train, I obtained 8 different lora files of 6.5 GB each, I think I should see a little bit similarity (It's like I'm typing elf and dwarves comes out :) . Is there something I missed? (trained with your sample 24 gb encoder json file via rtx 4090: 8 epochs, 40 repeats and 13 sample pictures) Need advice about this. Thanks
6.5 gb file is not lora. put them into models folder. they are full checkpoint. i can also give you private lecture if you are interested in
Thanks for all these training dreambooth details.(basicly kohya part) What about SD webui settings. I read membership exclusive posts and watched most of your youtube videos. But you didn't mention anywhere about SD webUI all deep details. Can you share also those parts? Such as in the video you are using different model, adding more ADetailer details.
Hello you are right. I don't have much info video regarding that. Currently for ADetailer I use 0.5 denoise, 70 steps and photo of ohwx man as a prompt if it is a realistic prompt. I should make a video
Hi, newbie question. What are the regularization images? Are they used to provide more creativity to the model to create different photos? Because one day I've fine-tuned a SDXL model using dreambooth, but I realized that they were very limited in producing new images, they were quite similar to the images I used during the training phase.
reg images will help model to keep its generalization thus it will be able to have more creativity
Why don't you use Realistic Vision model? I've heard that it is the best model for creating like real images, what's your opinion?
for SDXL i find SDXL 1.0 better than Realistic Vision XL. i compared
Hello, what is the difference if I load the trained safetensors file as lora or as checkpoint? Both work?
yes there are different. lora is just a part of a checkpoint. they works only with base checkpoint.
you, sir are truly something special. It is 2:44am and you answered my question in 5 minutes. If it is indeed you, Furkan, and not some CS clerk (which is still applaudable in terms of speed ofc), then my god you deserve every ounce of success you have had in the past year.
ty
Hi Furkan, could you briefly explain to me what exactly is meant by the calculation: "When training with regularization images, I did 1 epoch and 150 repeating. So more regularization images are used. And saved checkpoints at every 30 epochs. To make it that way calculate the number of steps you need to save. It is easy. 15 * 30 * 2 + 1" How does one calculate that. Really trying to understand that in order to tinker with the different settings myself.
Also that part I am having trouble understanding, sorry. The images are generated from epoch 150 so it is a little bit overtrained.