


Ovi - Generate Videos With Audio Like VEO 3 or SORA 2 - Run Locally - Open Source for Free
App Link
https://www.patreon.com/posts/140393220
Quick Tutorial
Info
App link : https://www.patreon.com/posts/140393220
Hopefully full tutorial coming soon
Ovi: Twin Backbone Cross-Modal Fusion for Audio-Video Generation
Project page : https://aaxwaz.github.io/Ovi/
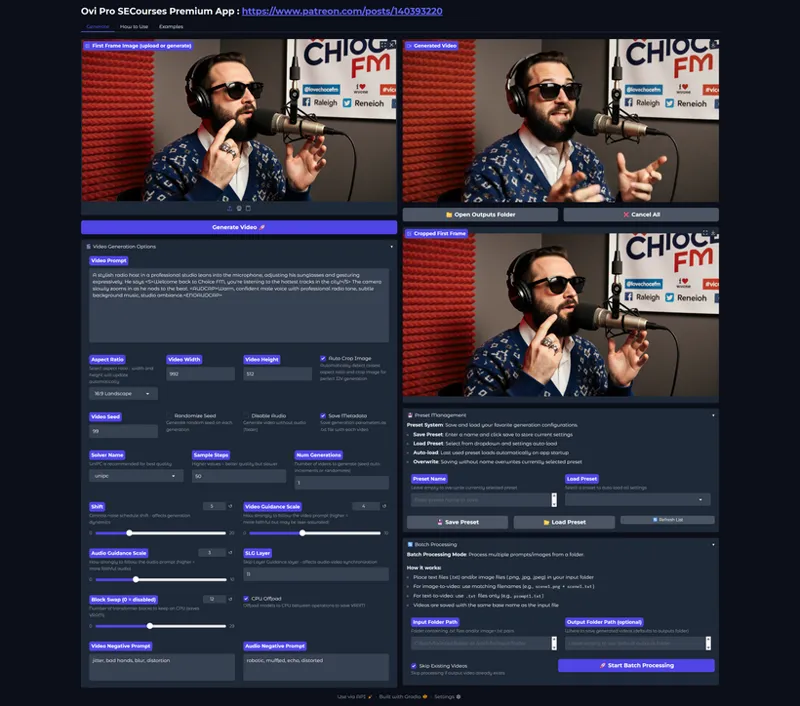
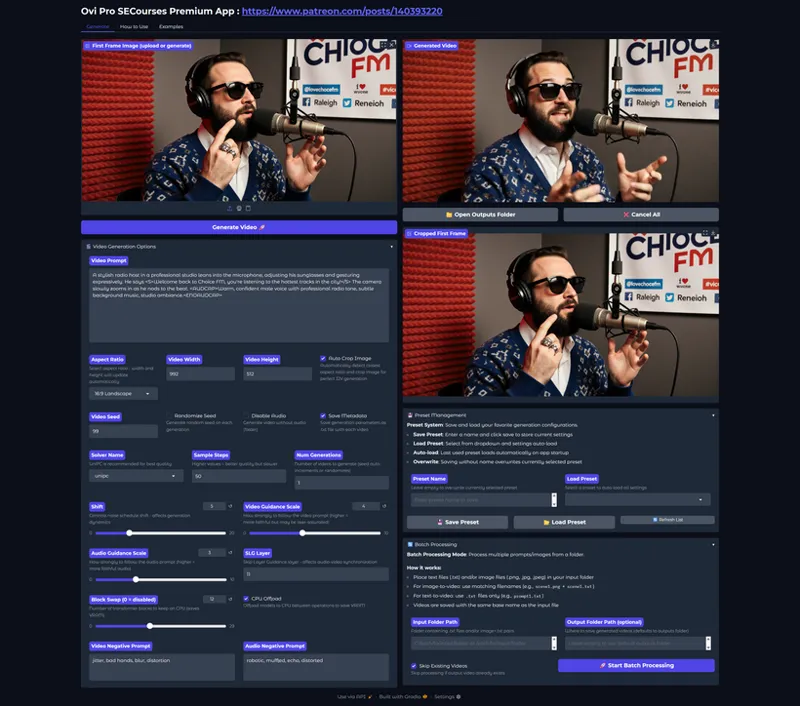
Full scale ultra advanced app for Ovi - an open source project that can generate videos from both text prompts and image + text prompts with real audio.
Project page is here : https://aaxwaz.github.io/Ovi/
I have developed an ultra advanced Gradio app and much better pipeline that fully supports block swapping
Now we can generate full quality videos with as low as 8.2 GB VRAM
Hopefully I will work on dynamic on load FP8_Scaled tomorrow to improve VRAM even further
So more VRAM optimizations will come hopefully tomorrow
Our implemented block swapping is the very best one out there - I took the approach from famous Kohya Musubi tuner
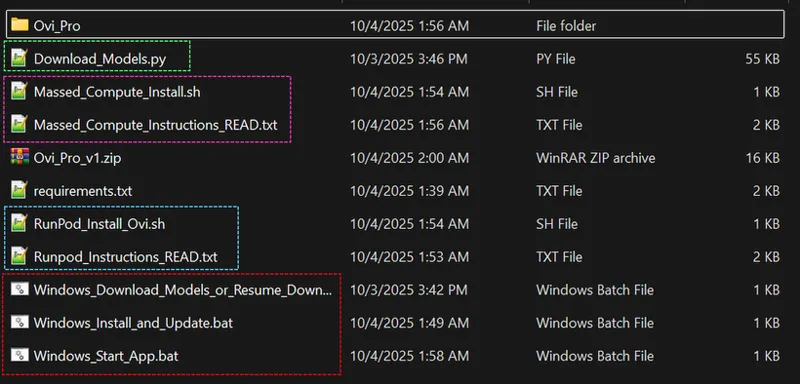
The 1-click installer will install into Python 3.10.11 venv and will auto download models as well so it is literally 1-click
My installer auto installs with Torch 2.8, CUDA 12.9, Flash Attention 2.8.3 and it supports literally all GPUs like RTX 3000 series, 4000 series, 5000 series, H100, B200, etc
All generations will be saved inside outputs folder and we support so many features like batch folder processing, number of generations, full preset save and load
This is a rush release (in less than a day) so there can be errors please let me know and I will hopefully improve the app
Look the examples to understand how to prompt the model that is extremely important
Look our below screenshots to see the app features
RTX 5090 can run it without any block swap with just cpu-offloading - really fast
50 Steps recommended but you can do low too like 20
1-Click to install on Windows, RunPod and Massed Compute
More Info from Developers
High-Quality Synchronized Audio
We pretrained from scratch our high-quality 5B audio branch using a mirroring architecture of WAN 2.2 5B, as well as our 1B fusion branch.
Data-Driven Lip-sync Learning
Achieving precise lip synchronization without explicit face bounding boxes, through pure data-driven learning
Multi-Person Dialogue Support
Naturally extending to realistic multiple speakers and multi-turn conversations, making complex dialogue scenarios possible
Contextual Sound Generation
Creating synchronized background music and sound effects that match visual actions
OSS Release to Expedite Research
We are excited to release our full pre-trained model weights and inference code to expedite video+audio generation in OSS community.
Human-centric AV Generation from Text & Image (TI2AV)
Given a starting first frame and text prompt, Ovi generates a high quality video with audio.
All videos below have their first frames generated from an off-the-shelf imagen model.
Human-centric AV Generation from Text (T2AV)
Given a text prompt only, Ovi generates a high quality video with audio.
Videos generated include large motion ranges, multi-person conversations, and diverse emotions.
Multi Person AV Generation from Text or Image (TI2AV)
Given a text prompt with optional starting image, Ovi generates a video with multi person dialogue.
Sound effect (SFX) AV Generation from Text w or w/o Image (TI2AV or T2AV)
Given a text prompt with optional starting image, Ovi generates a video with high-quality sound effects.
Music Instrumeent AV Generation from Text w or w/o Image (TI2AV or T2AV)
Given a text prompt with optional starting image, Ovi generates a video with music.
Limitations
All models have limits, including Ovi
Video branch constraints. Visual quality inherits from the pretrained WAN 2.2 5B ti2v backbone.
Speed/memory vs. fine detail. The 11B parameter model (5B visual + 5B audio + 1B fusion) and high spatial compression rate balance inference speed and memory, limiting extremely fine-grained details, tiny objects, or intricate textures in complex scenes.
Human-centric bias. Data skews toward human-centric content, so Ovi performs best on human-focused scenarios. The audio branch enables highly emotional, dramatic short clips within this focus.
Pretraining only stage. Without extensive post-training or RL stages, outputs vary more between runs. Tip: Try multiple random seeds for better results.