








How To Convert 24 GB FP16 Fine Tuning / DreamBooth FLUX Checkpoints into 12 GB FP8 Checkpoints Tutorial
As you already know, FLUX Fine Tuning / DreamBooth is yielding the very best results compared to FLUX LoRA training. Here a detailed public post about it : https://www.patreon.com/posts/113970485
When you look the above post, you will see Fine Tuning / DreamBooth always yields way better results than any LoRA training.
Perhaps the biggest disadvantage of Fine Tuning is that its saved checkpoints are FP16 thus each one is taking 23.8 GB HDD space
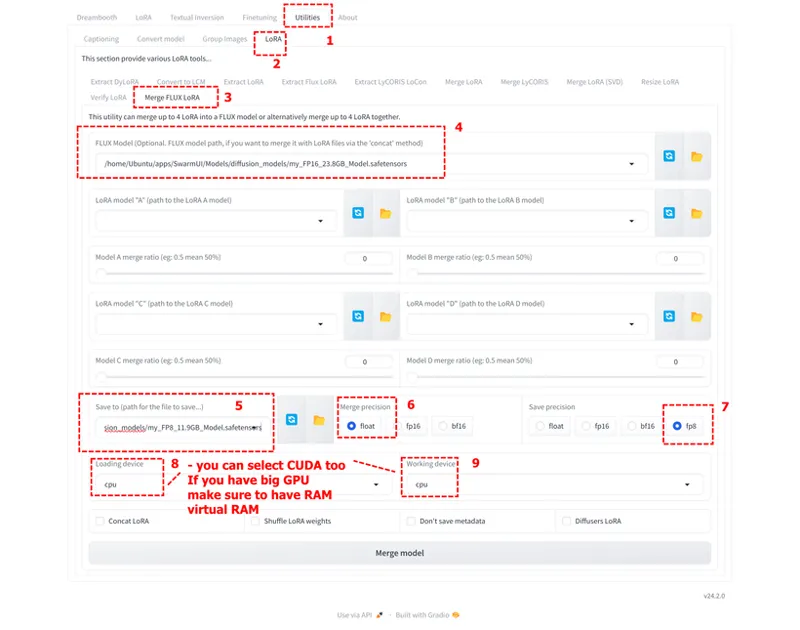
But with using Kohya GUI, you can convert FP16 models into FP8 and there is no visible quality loss - the size gets down to half 11.9 GB
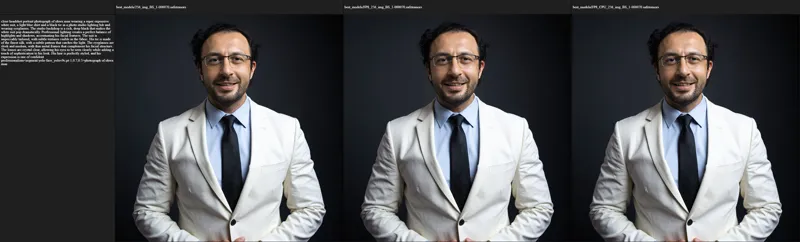
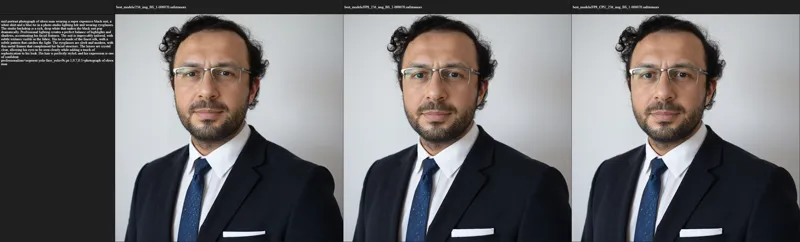
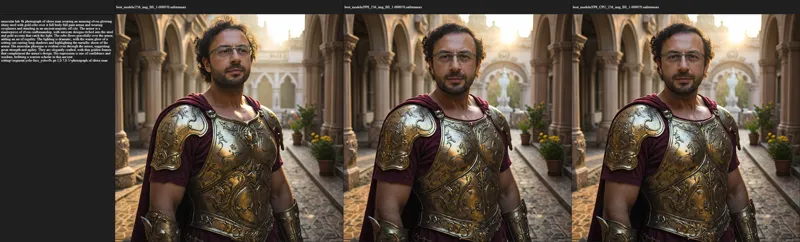
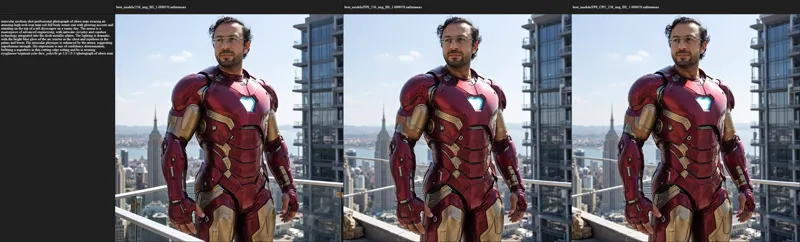
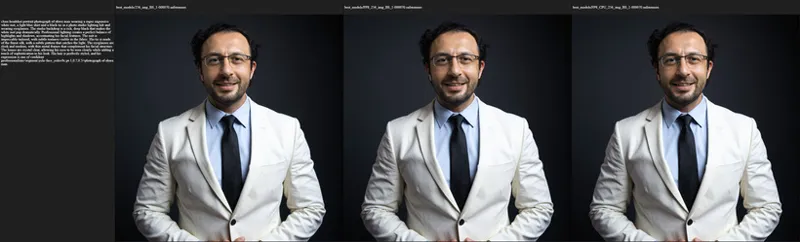
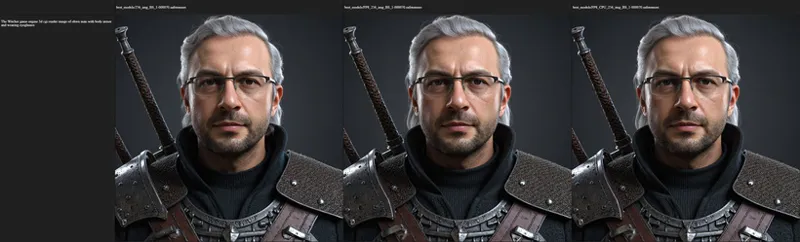
The first image above shows how to convert into FP8 and the second grid image shows there is no visible difference
Check all the images
And here how to do full proper Fine Tuning / DreamBooth as low as with 6 GB GPU : https://www.patreon.com/posts/112099700
Left one is FP16, middle is FP8 made with CUDA, right is FP made with CPU - no diff between CUDA and CPU

Comments (20)
Is there a way to do all that programmatically using Kohya_ss?
Hi, when i try to merge model i got error: Traceback (most recent call last): File "E:\KOHYA_FLUXD\kohya_ss\sd-scripts\networks\flux_merge_lora.py", line 765, in merge(args) File "E:\KOHYA_FLUXD\kohya_ss\sd-scripts\networks\flux_merge_lora.py", line 626, in merge save_to_file(args.save_to, flux_state_dict, save_dtype, sai_metadata, args.mem_eff_load_save) File "E:\KOHYA_FLUXD\kohya_ss\sd-scripts\networks\flux_merge_lora.py", line 49, in save_to_file save_file(state_dict, file_name, metadata=metadata) File "E:\KOHYA_FLUX\kohya_ss\venv\lib\site-packages\safetensors\torch.py", line 286, in save_file serialize_file(_flatten(tensors), filename, metadata=metadata) safetensors_rust.SafetensorError: Error while serializing: IoError(Os { code: 5, kind: PermissionDenied, message: "Access is denied." }) 10:40:25-479873 INFO Done merging... Dreambooth training works fine with my kohya installation bot not merging, can you help with this?
It is your computer, your windows not allowing. Check your folder permissions python permissions
What is your suggestion for optimizing models for 3000/Ampere GPUs? I understand that FP8 isn't supported. Currently running a 3090.
FP8 works but just not speed up as in rtx 4000 series. so it will be same speed as long as fitting into VRAM.
any converters to nf4?
not that i know any
Thank you for this. I am not able to run the finetuned FP8 model in my 3090. However, I was trying to merge 4 Flux Lora together, but it was resulting in a full 23GB model. Is there a setting to use to merge multiple Flux Lora into one?
yes you can merge into one via kohya gui
Hello massed compute no a6000 available what is happening?
Yesterday i finished finetune 11800 imges on 1 epoch , takes 42 hours on 4090 but the model is 22 gb and forgeui struggling with it , use 24gb vram and 50gb ram !! For 1 generation, I thought i waste my time, but i will try this method, Thank you
this really helps. also your duration looks too much for 4090. you should get like 6 second / it
can you please elaborate on why fp8 and not Q8_0 gguf? Q8 seems to be closer to fp16 and is also 12GB, check this out: https://www.reddit.com/r/StableDiffusion/comments/1eso216/comparison_all_quants_we_have_so_far/?rdt=53989 From the comments to that post: https://imgsli.com/Mjg3ODgy/2/3
Because Kohya doesn't have it yet. I think ComfyUI might have but not sure
This works great! Did a comparison in Photoshop to see if there's any difference. There is none.
awesome
So I can't train on fp8 dev model? Currently running dreambooth finetuning on fp8 model with Kohya, runs fine but result won't be any good then?
you cant train but you can use trained model as fp8 there is absolutely 0 issues.
Do you mean you convert your checkpoint after it's saved/finished training from FP16 to FP8? There's a flux1-dev-fp8.safetensors and flux1-schnell-fp8.safetensors. Can a Flux Dreambooth (or Lora) be trained on either of those fp8 models while still being high enough quality, and will doing that use a lot less VRAM than training against the 22 GB flux1-dev.sft model (that I asume is fp16)?
these are after training. fine tuning need fp16 base model and training is done in 16 bit precision