

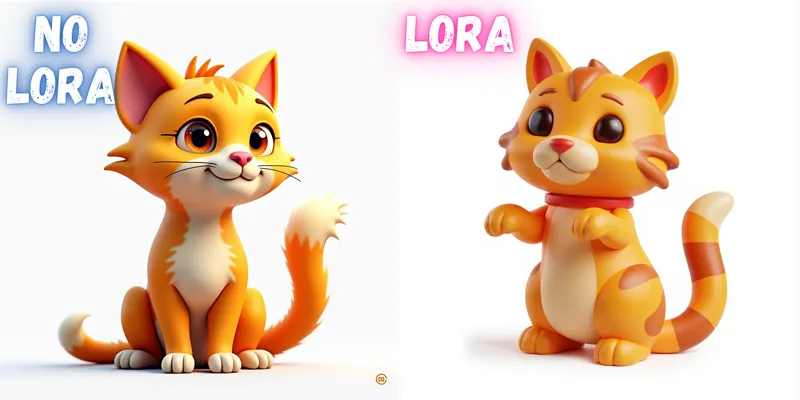
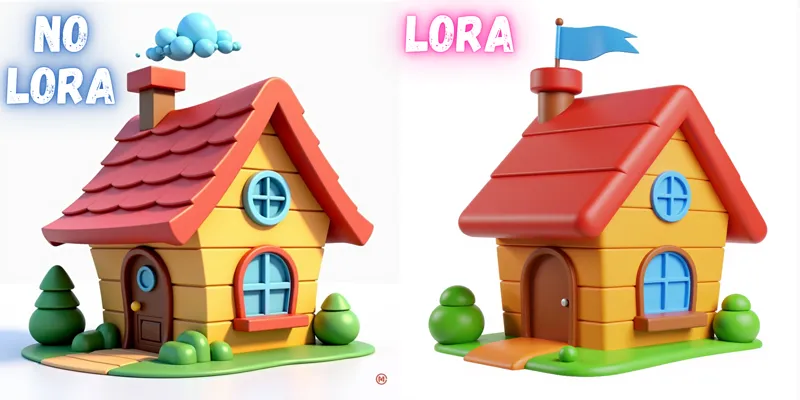


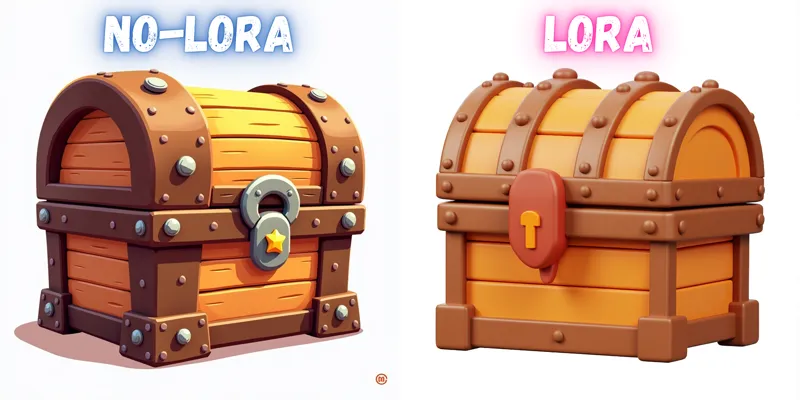
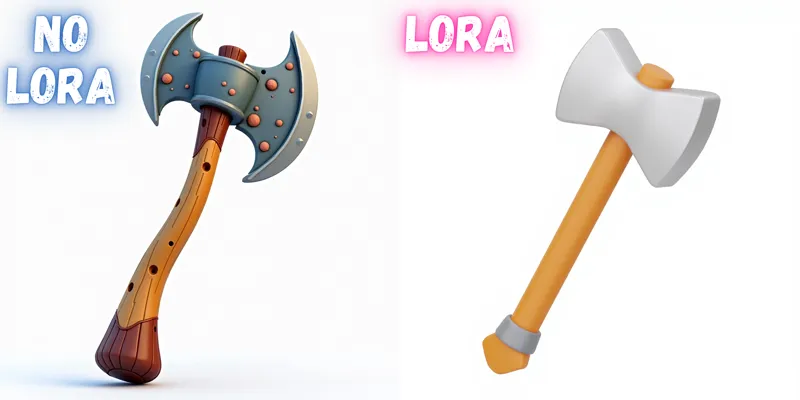


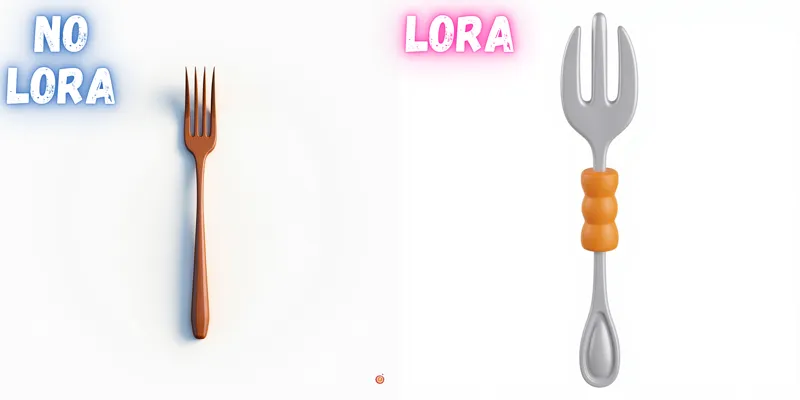

SECourses 3D Render for FLUX LoRA Model Published on CivitAI - Style Consistency Achieved - Full Workflow Shared on Hugging Face With Results of Experiments - Last Image Is Used Dataset
CivitAI Link : https://civitai.com/models/731347
Hugging Face Link : https://huggingface.co/MonsterMMORPG/3D-Cartoon-Style-FLUX
SECourses 3D Render for FLUX LoRA Model Published on CivitAI - Style Consistency Achieved - Full Workflow Shared on Hugging Face With Results of Experiments - Last Image Is Used Dataset
Comments (16)
Hi, Furkan! Tell me, please, do you have any instructions on how to make prompts correctly for trained Loras? If I generate images with Lora with the initial prompts that I used to train this Lora, then images with the style I need are generated. But if I try to generate an image with Lora, but in the description I write only "ohwx style" and a description of another item that I want to generate in Lora's style, then the result is a generation in the usual Stable Diffusion style, as if without Lora. Do I understand correctly that you need a very detailed description in the prompt, and not just, for example, "ohwx style car"? In this case, how to choose the right prompt for a trained Laura, so as not to lose the trained style? The main idea is to repeat exactly the style of the images on which Laura was trained.
for style loras i recommend this. describe the style as much as possible in the prompt. it really helps to generate it. so lets say i trained digital art. so it will be like: image of a car in ohwx digital art style. (here describe what you want) (here you describe style as much as possible) e.g. OHWX line art coloring book featuring Organized & Exciting Packing Scene. A cozy bedroom filled with warm light, where a large open suitcase rests on the bed, half-packed for an exciting journey ahead. A neatly folded stack of clothes, a camera, a travel guidebook, and a passport are arranged nearby. A sturdy backpack leans against the side of the bed, ready for adventure. On the nightstand, a cup of coffee steams gently next to a handwritten checklist of essentials. The window in the background shows a sunrise, hinting at an early departure. The scene captures the anticipation of a long trip, with carefully selected belongings waiting to be tucked inside. The composition features a flat perspective with no deep backgrounds, focusing on foreground elements for easy visibility. Objects are arranged logically and naturally, with uniform line thickness and delicate, consistent strokes. The design is uncluttered, with minimal shading and no excessive textures or patterns, resembling traditional ink drawings. The overall style is crisp and polished, neat and tidy, with clean thin lines, simple style
Hello, I saw your Flux style training tutorial on civitai. When I see the grid results I have a question, why are you testing the following prompts [ "a ohwx render of car" ] and [ "a ohwx car" and "a ohwx style car image"] and ["a car rendered in ohwx 3d car"], What is the purpose of testing these prompts?
it provides info regarding how overfit model is, how destroyed its capability and generalization is
Should we use the same learning rate for style training as for character training?
i used same. LR changes when you use multiple GPUs
Hello, have you tested the Lora training parameters for interior architectural styles? I've been failing at training.
nope but if you have a project budget i can do research for you
Great job done! Appreciated for making style training and not person!
thank you hopefully more to come
thank you very much, now i will see it. i have an AI fashion startup and we work with several brands some very important and i can't use many loras in the same flow because it damages the image. we need to train people, clothes, and a neutral gray background in the same lora to do the shooting for the ecommerce
well if you have a budget i can do consultation and research
is there any possibility of making a dreambooth in flux at the moment?
yes it is my this week research hopefully
hey furkan! do you know where there is information to train several concepts in the same lora for flux? is it different from how it is done in sd xl? do you need regularization images? i want to train several clothing items, several characters and a neutral gray background of ecommerce.
in this video i explain multi concept logic with repeating : https://youtu.be/nySGu12Y05k you dont need reg images. it is not difference than sdxl but flux much more powerful and robust